Any financial analysis starts with data. Whether you want to analyze a stock, build a portfolio, measure risk, create a valuation model or develop trading strategies, the first step is always the same: obtaining financial data.
You could download data manually from websites such as Yahoo! Finance or Investing.com, but this quickly becomes tedious and time-consuming. It also limits the amount of data you can work with.
R allows us to automate this process and retrieve large amounts of financial information in just a few lines of code.
In this article, Hadrien PUCHE (ESSEC Business School, Grande École Program, Master in Management, 2023-2027) will help you to:
- Download historical stock prices and market indices with R
- Explore, clean, and visualize
xtstime-series data - Compute basic statistics and historical distributions
- Compare multiple securities
- Build the foundation needed for more advanced financial analysis
But first, what financial data can we actually download?
Financial professionals use many different categories of data across individual assets as well as portfolios and funds.
Market data (Easily downloadable for free via Yahoo! Finance)
- Individual asset prices (e.g., individual stocks, corporate bonds)
- Portfolios and funds (e.g., ETFs, mutual funds)
- Currency exchange rates (e.g., EUR/USD)
- Market indices (e.g., S&P 500)
Macroeconomic data (Available via the St. Louis Fed – FRED)
- Inflation and Consumer Price Index (CPI)
- Interest rates and bond yields
- GDP growth and unemployment
Not all data sources are freely available. Many professional investors rely on paid platforms such as Bloomberg or FactSet to access fundamental accounting data (revenue, cash flows) and alternative data (satellite imagery, sentiment). Fortunately, market prices and macroeconomic indicators can easily be accessed for free using R for research and learning purposes.
While you can download macroeconomic data using specialized packages like fredr, we will keep things simple in this article and focus purely on extracting and modeling market prices using the open-source quantmod package.
A step-by-step guide
Follow the next steps to download your first financial dataset with R.
Step 1: Instal the required packages
If you have not yet installed R, refer to the setup guide published earlier in this series to configure your execution environment (RStudio).
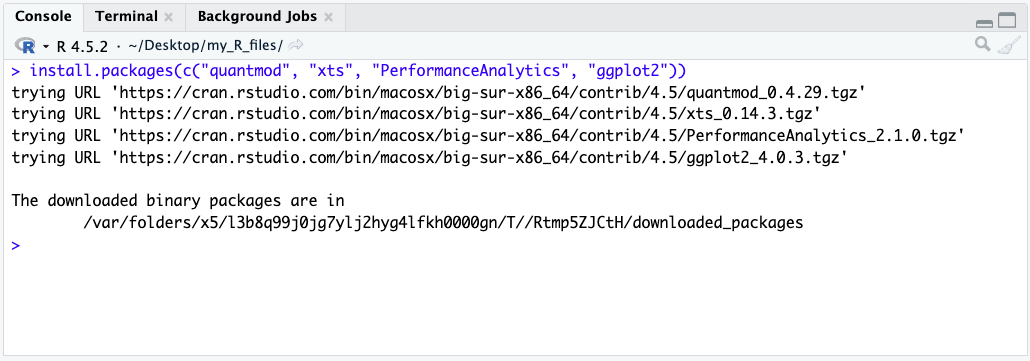
Once your environment is ready, install the required packages by running this in your console (you only need to do this once):
install.packages(c("quantmod", "PerformanceAnalytics"))Here is what these packages do:
- quantmod: Short for Quantitative Financial Modelling Framework, it is a widely used R package for downloading and analyzing financial market data, including data from Yahoo! Finance.
- xts: Short for eXtensible Time Series, this package is automatically installed with quantmod. It provides data structures specifically designed for time-indexed data.
- PerformanceAnalytics: A package of econometric functions used to calculate returns and risk metrics.
Step 2: Import your R packages
Most financial analysis scripts begin by loading the packages required for the analysis using the library() function.
Create a new R script file. You can also save it wherever you want. Paste the following script and run it (as a reminder, you need to select the code you want with your mouse before running it):
library(quantmod)
library(PerformanceAnalytics)
Step 3: Download your first data
To download financial data, we use ticker symbols, which identify securities or market instruments within a given exchange or data provider. For example, AAPL represents Apple.
We will use the getSymbols() function. By passing arguments to the function, we can customize the output. Setting auto.assign = FALSE assigns the dataset directly to a variable that we can name aapl_data.
Let us download daily data for Apple’s stock price over the last five years (from 01/01/2019 to 31/12/2024 at that time)t.
# Download historical Apple stock data
aapl_data <- getSymbols("AAPL", src = "yahoo", from = "2019-01-01", to = "2024-01-01", auto.assign = FALSE)

# Display the first 5 rows
head(aapl_data, 5)
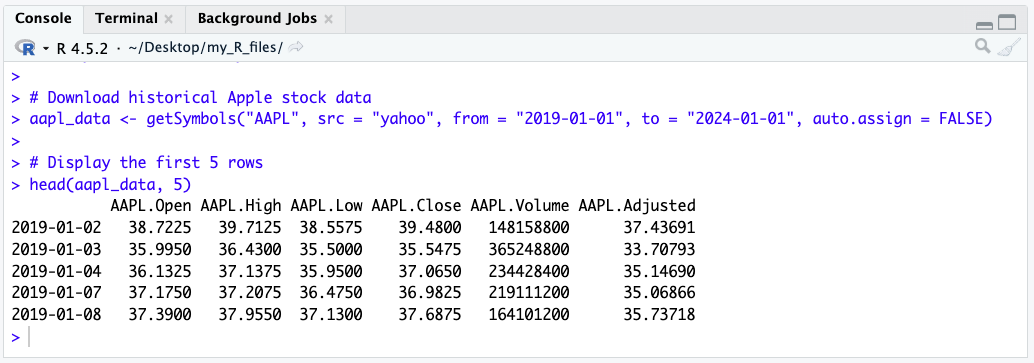
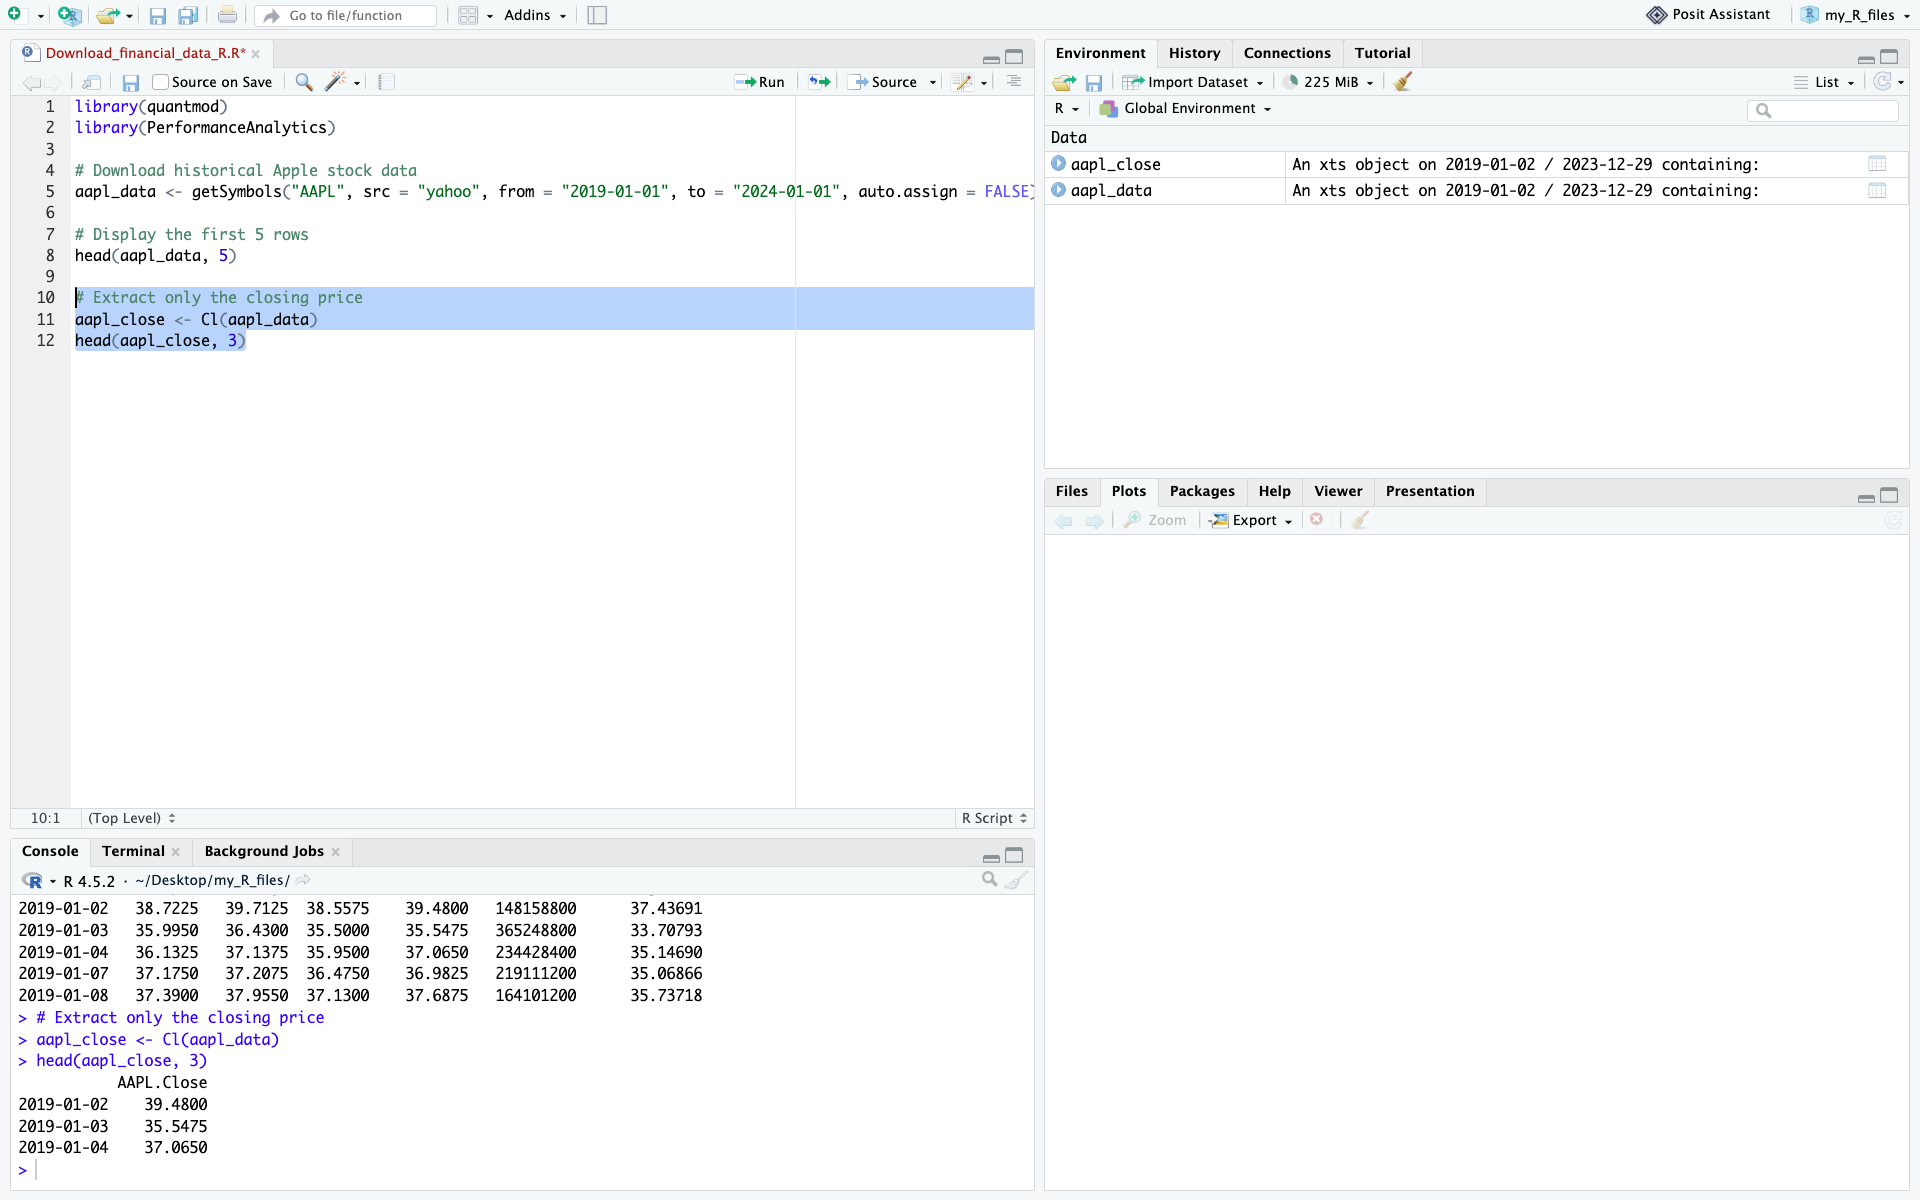
You will obtain this xts table with the following columns:
- Open: opening price at the beginning of the trading day
- High: highest price during the trading day
- Low: lowest price during the trading day
- Close: closing price at the end of the trading day
- Volume: transaction volume during the trading day
- Adjusted: closing price adjusted for stock splits and dividends
To keep things simple for this guide, we will focus strictly on the raw Close price. quantmod provides a convenient helper function called Cl() that instantly extracts just the closing price column from the dataset.
# Extract only the closing price
aapl_close <- Cl(aapl_data)
head(aapl_close, 3)
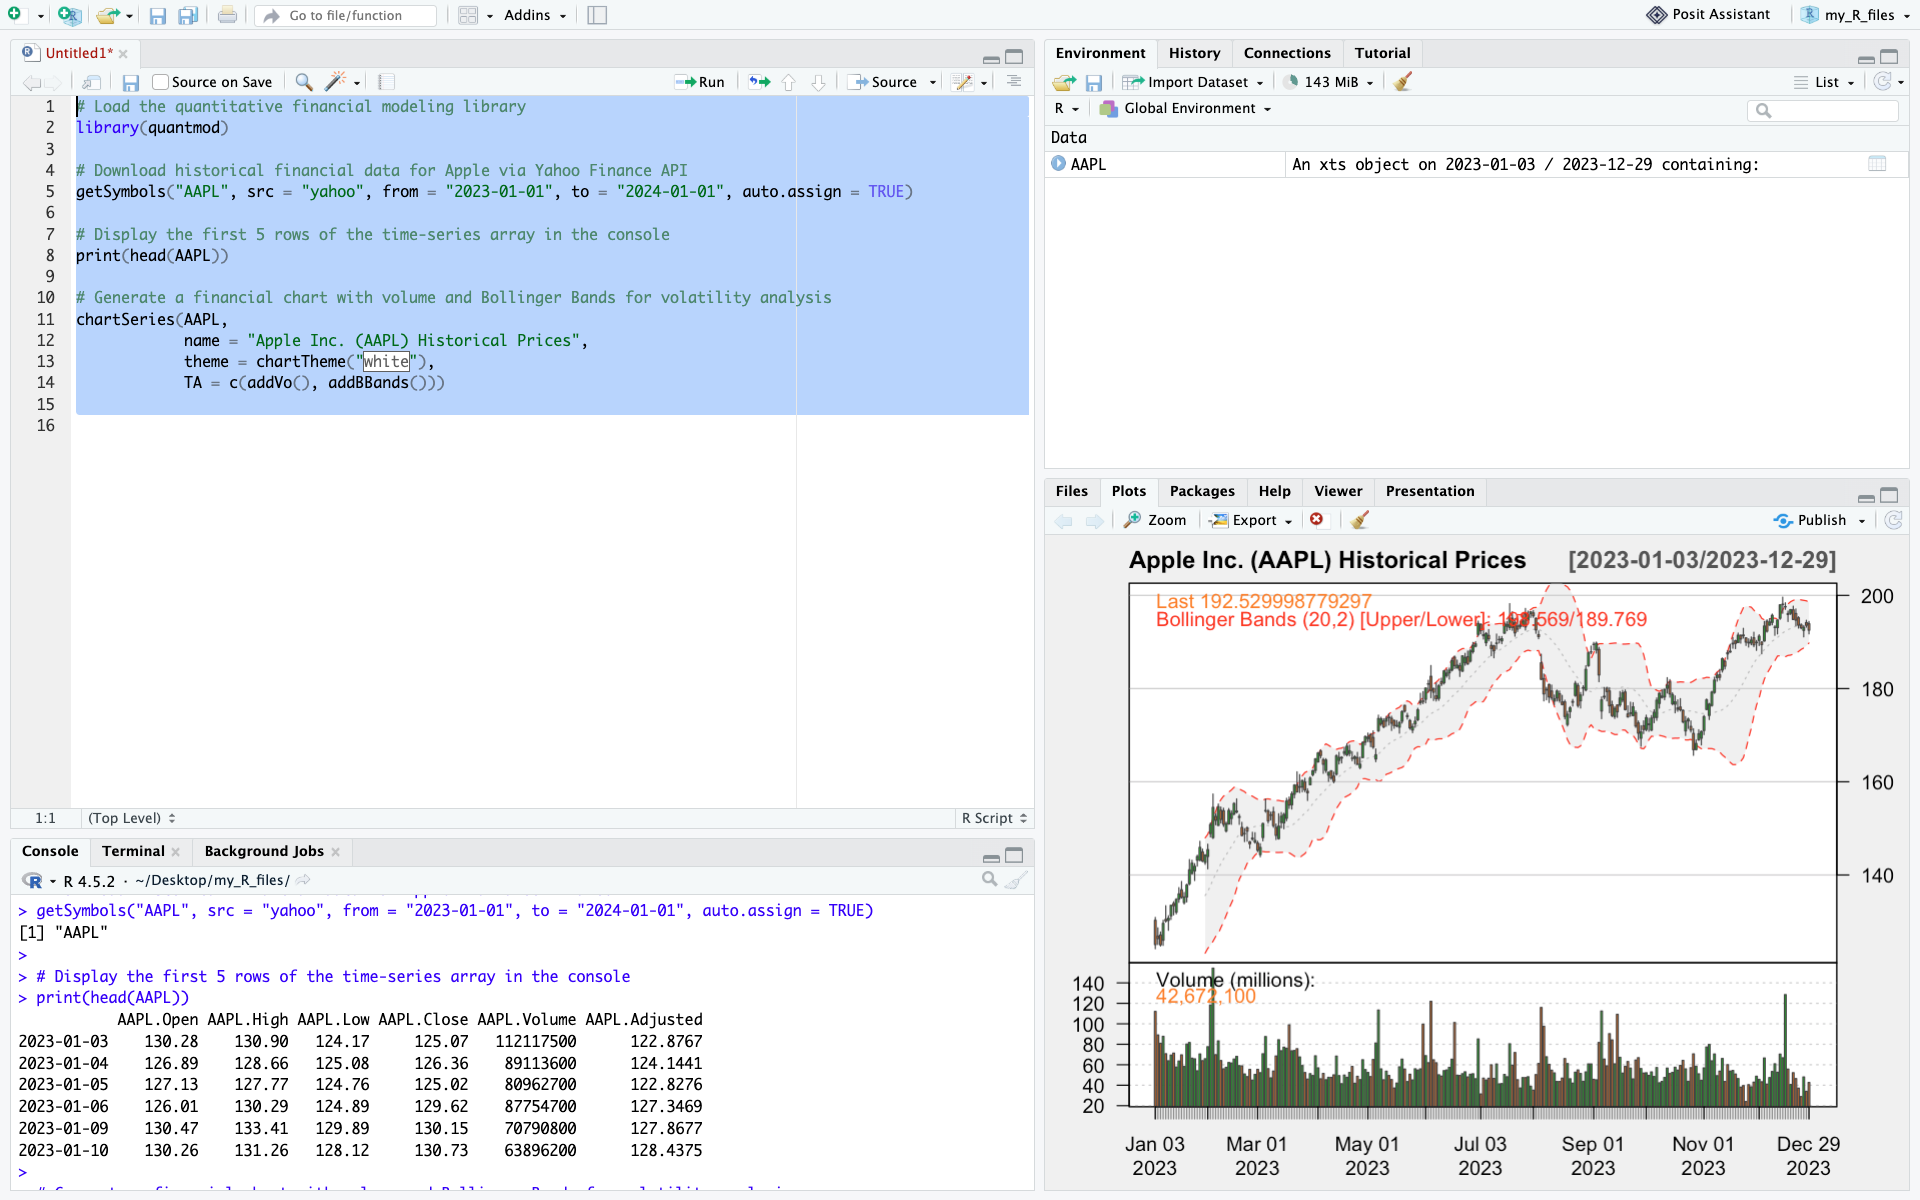
Add this code to your script, then highlight it with your mouse, and press run. Your RStudio should now display this:
Step 4: Use more precise queries for historical context
As financial analysts, we routinely extract specific timeframes to understand how assets behave under macroeconomic stress. Because our data is stored as an xts object, R makes it incredibly easy to slice time-series data using date ranges.
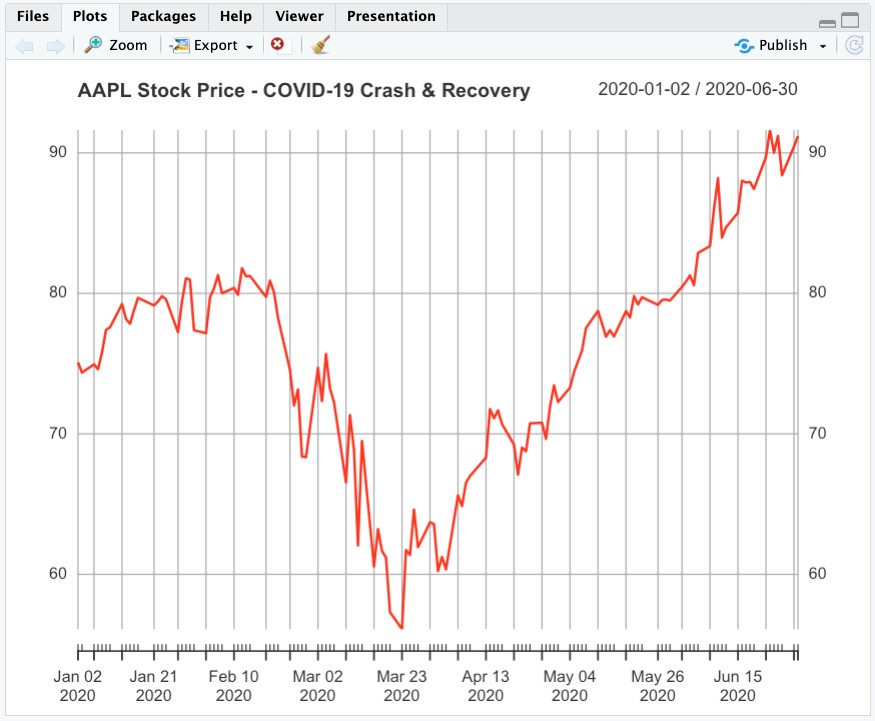
For example, examining the COVID-19 market shock in early 2020 provides a useful illustration of extreme market volatility. Let’s isolate Apple’s stock specifically during the COVID-19 market shock and initial recovery (January to June 2020):
# Isolate the COVID-19 crash using xts date subsetting (YYYY-MM-DD/YYYY-MM-DD)
covid_crash <- aapl_close["2020-01-01/2020-06-30"]

# Plot the isolated data
plot(covid_crash, main = "AAPL Stock Price - COVID-19 Crash & Recovery", col = "red", lwd = 2)
Step 5: Download the data for multiple stocks at the same time
Downloading multiple stocks is necessary for financial analysis that often requires comparing securities, analyzing sectors, or building a portfolio. Instead of issuing separate requests and risking misaligned dates, we can fetch all tickers at once.
Let’s download the data for six of the largest US banks: JPMorgan Chase, Bank of America, Wells Fargo, Citigroup, Goldman Sachs, and Morgan Stanley. Analyzing this sector is a classic way to measure the impact of interest rates on the broader economy.
# Define the major US bank tickers
bank_tickers <- c("JPM", "BAC", "WFC", "C", "GS", "MS")

# Download data into the global environment
getSymbols(bank_tickers, src = "yahoo", from = "2019-01-01", to = "2024-01-01")

# Extract only the closing prices and merge them into a single matrix
bank_prices <- merge(Cl(JPM), Cl(BAC), Cl(WFC), Cl(C), Cl(GS), Cl(MS))

head(bank_prices, 3)
The result is an xts object in which each column represents a stock and each row corresponds to a trading date.
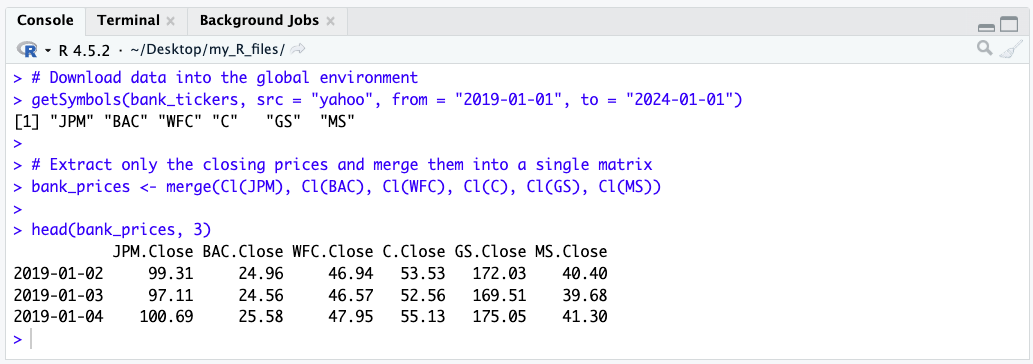
This table format is ideal for portfolio analysis and benchmarking. To save it for external use, you can export it as a CSV file:
# Save the data frame as a CSV file
write.csv(as.data.frame(bank_prices), file = "us_banks_data.csv")
Now that you have successfully downloaded your financial data, let’s see how you can clean it and then use it.
Inspecting and cleaning the dataset
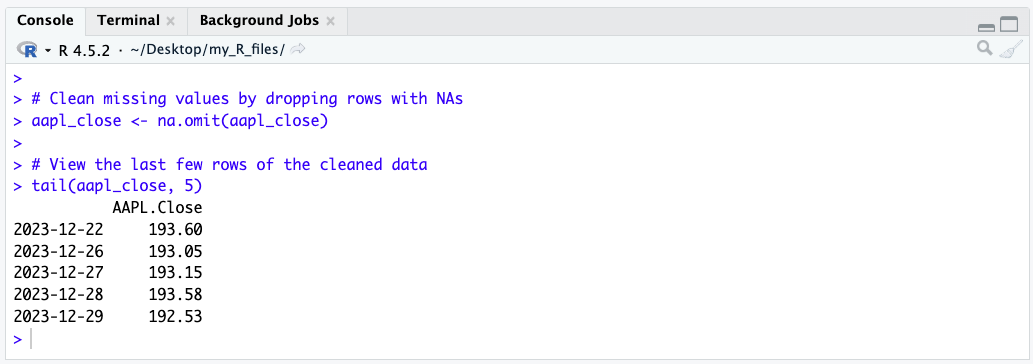
Financial datasets may contain missing values (NA) for various reasons, including trading suspensions, differences in trading calendars, listing dates, or data-provider issues. Missing observations should be identified before computing returns or risk measures, as they may affect subsequent calculations. For this introductory example, we simply remove rows containing missing values using na.omit(). In applied financial analysis, however, the appropriate treatment depends on the source of the missing data and the objective of the analysis.
In R, we can easily remove any rows containing missing data using the na.omit() function.
# Check for missing values (returns the total count)
sum(is.na(aapl_close))

# Clean missing values by dropping rows with NAs
aapl_close <- na.omit(aapl_close)

# View the last few rows of the cleaned data
tail(aapl_close, 5)
Vizualizing your data
Let’s create our first chart to visualize the evolution of Apple’s stock price using the chartSeries() function, which is built specifically for financial time series.
chartSeries(aapl_close,
            name = "Apple Stock Price",
            theme = chartTheme("white"),
            TA = NULL) # TA = NULL removes technical indicators for a clean chart
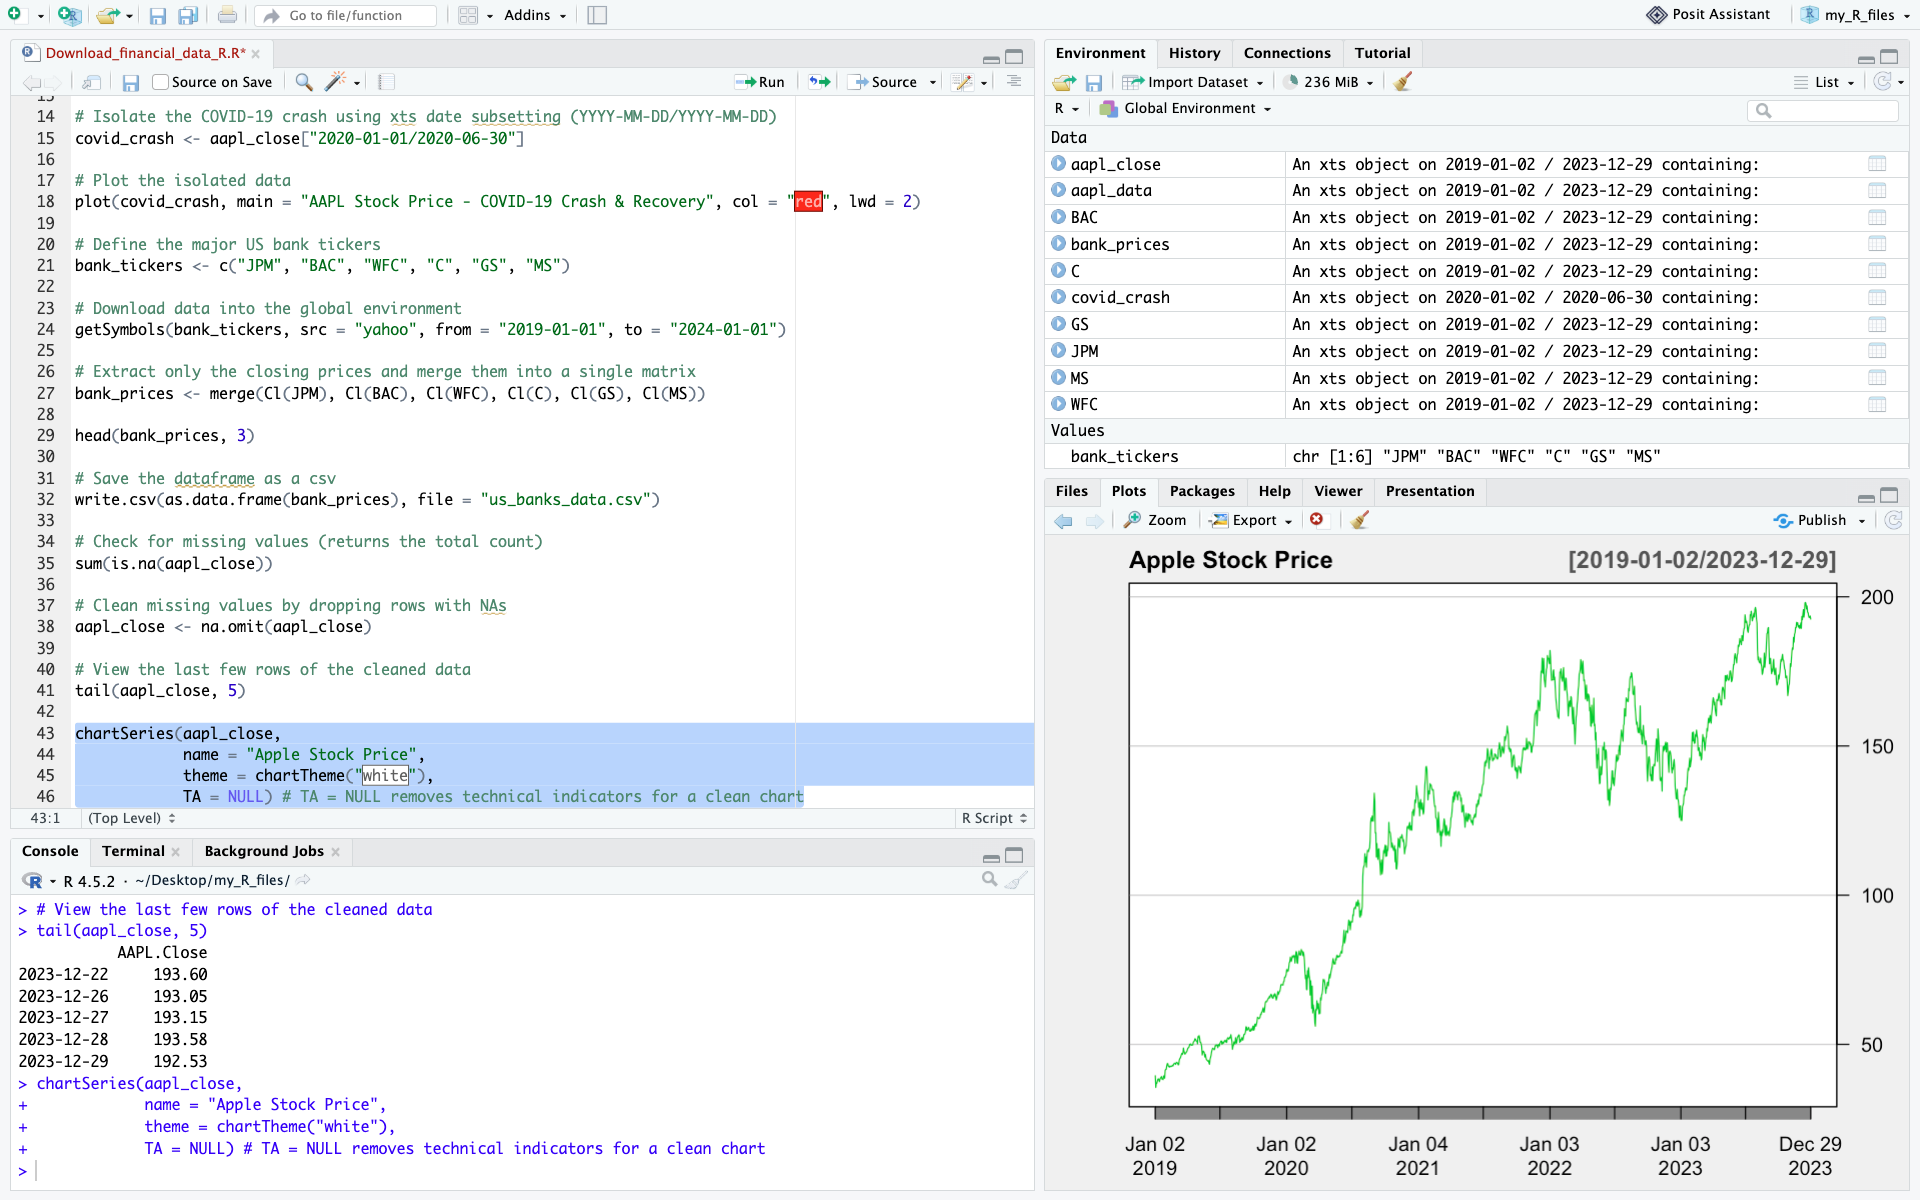
We have now:
- Downloaded market data from Yahoo! Finance
- Extracted the closing price and cleaned the data
- Created a time-series plot to visualize stock prices
These core steps form the basis of empirical financial research and quantitative models.
Computing basic statistics and historical distributions
To evaluate stock performance and risk, we compute basic descriptive statistics. First, we calculate daily returns using the Return.calculate() function from the PerformanceAnalytics package.
# Calculate daily percentage returns (and remove the first NA row)
aapl_returns <- Return.calculate(aapl_close)
aapl_returns <- na.omit(aapl_returns)

# Compute summary statistics
mean_return <- mean(aapl_returns)
volatility <- sd(aapl_returns)
skew <- skewness(aapl_returns)
kurt <- kurtosis(aapl_returns)

print(paste("Mean Daily Return:", round(mean_return, 5)))
print(paste("Daily Volatility (Std Dev):", round(volatility, 4)))
Plotting historical distributions
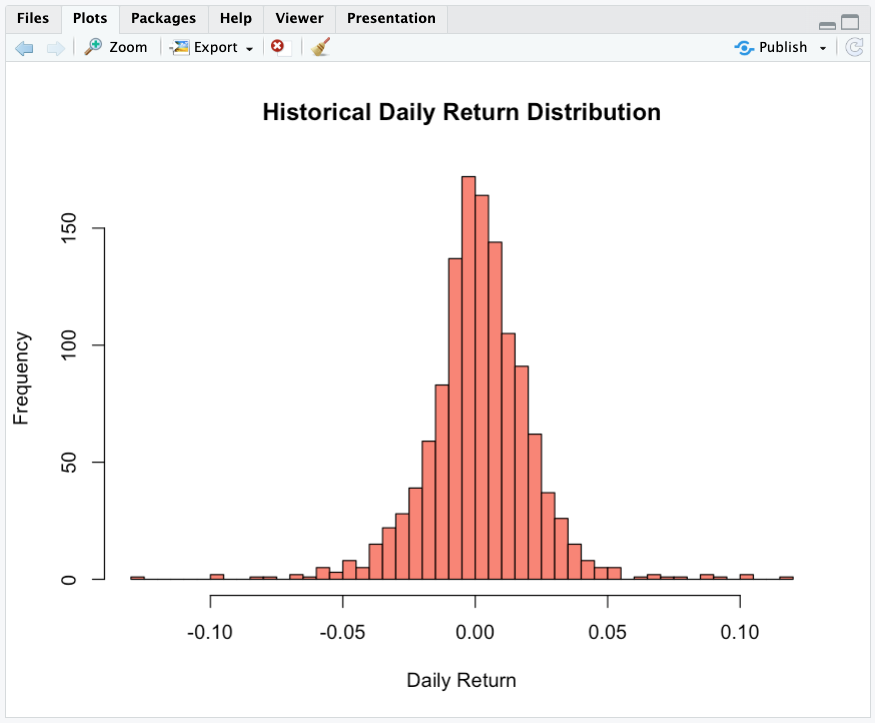
Histograms display the frequency distribution of daily returns, helping us inspect distribution symmetry and tail risks.
# Return distribution histogram
hist(aapl_returns, breaks = 50, col = "salmon", main = "Historical Daily Return Distribution", xlab = "Daily Return")
Normalizing stock prices and computing returns
All stocks have different nominal prices. If Tesla trades at $350 and Nvidia at $220, it does not mean that Tesla performed better. To establish an accurate comparison, we execute two fundamental computations:
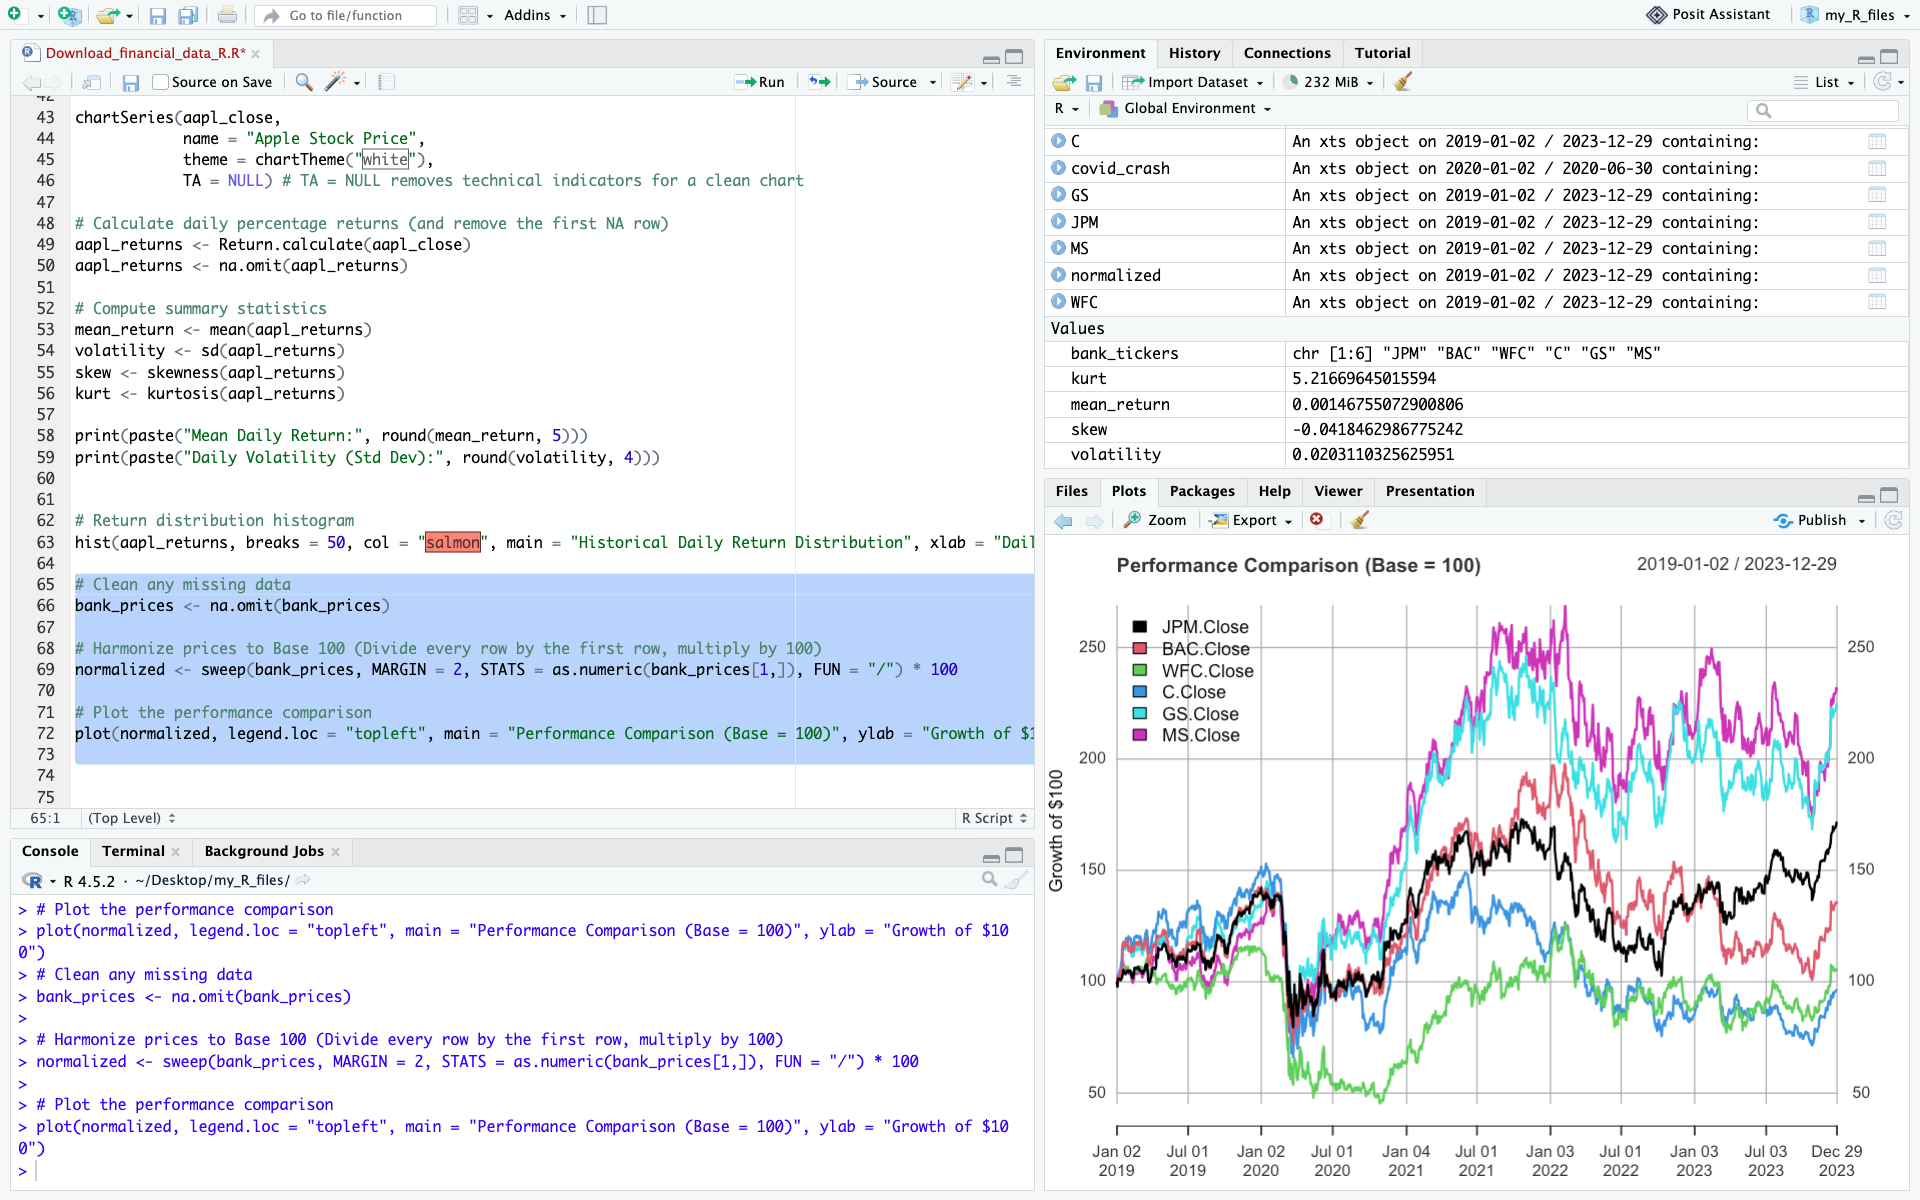
- Price normalization: We normalize all historical time series to a base index of 100, ensuring a standardized starting point.
- Return calculation: We compute periodic returns to measure performance independently of the nominal price level.
# Clean any missing data
bank_prices <- na.omit(bank_prices)

# Harmonize prices to Base 100 (Divide every row by the first row, multiply by 100)
normalized <- sweep(bank_prices, MARGIN = 2, STATS = as.numeric(bank_prices[1,]), FUN = "/") * 100

# Plot the performance comparison
plot(normalized, legend.loc = "topleft", main = "Performance Comparison (Base = 100)", ylab = "Growth of $100")
We can also compute daily returns across all stocks in one line:
bank_returns <- na.omit(Return.calculate(bank_prices))
head(bank_returns, 3)
This is a standard technique used by portfolio managers and equity analysts to compare growth trajectories.
Common pitfalls
When working with market data in R, beginners often run into the same issues:
- Using the wrong ticker symbol
- Comparing stocks without normalizing prices (Base 100)
- Forgetting that markets are closed on weekends and holidays
- Failing to clean and handle missing values (
NA) usingna.omit() - Using raw closing prices when adjusted prices are required: for long-term performance analysis, adjusted prices are generally preferable because they account for stock splits and dividends.
Overall, don’t forget to always inspect and clean your data before starting your analysis.
Exercises
Exercise 1: Basic data retrieval and price visualization (RACE)
Ferrari N.V. (RACE) presents an interesting case study in market dynamics: it is a car manufacturer that acts as a high-end luxury franchise. Its deliberate production scarcity, multi-year order backlogs, and immense pricing power decouple it from typical automotive boom-and-bust cycles.
Using the ticker symbol RACE, download the last five years of daily market data.
Your tasks:
- Use the appropriate R functions to display the first 5 rows and the last 5 rows of the dataset to verify data integrity.
- Extract the closing price and generate a line chart plotting the price over the entire 5-year period. Observe how its price trajectory reflects Ferrari’s distinctive positioning at the intersection of the automotive and luxury industries.
Exercise 2: time-series extraction and volume analysis on Tesla (TSLA)
Tesla is renowned for its high historical volatility and massive retail trading interest. The 2022-2024 window was particularly eventful for growth and electric vehicle stocks, marked by shifting supply chains and a rapid rise in interest rates.
Using the ticker symbol TSLA, extract the market data for the precise calendar period from January 1, 2022, to December 31, 2024 (using the from and to parameters).
Your tasks:
- Identify the peak (highest closing price) and the trough (lowest closing price) over this period using the
max()andmin()functions. - Extract the Volume column (using
Vo()) and calculate the average daily trading volume, a fundamental metric used by analysts to assess market liquidity.
Exercise 3: Comparative performance and risk profiling on Chinese tech companies
Chinese technology stocks often experience unique market cycles driven by distinct domestic regulatory environments and macroeconomic factors. Using the last five years of daily market data, compare the performance and risk characteristics of the following three US-listed ADRs:
- Alibaba (BABA)
- Baidu (BIDU)
- PDD Holdings (PDD)
Questions:
- Which stock achieved the highest total cumulative return?
- Which stock was most volatile (highest standard deviation of daily returns)?
- Which one offered the best risk-adjusted profile over the period? Use the harpe ratio or any risk-adjusted measure
Download the solutions
To help you check your work and experiment further, you can download the complete R Script containing the full code, charts, and commentary for all exercises.
Download Solutions (.R Script)
What’s next?
Now that you know how to download financial data, compute returns, and analyze basic performance and risk measures in R, you are ready to delve into more advanced quantitative and corporate finance topics.
If you want to learn more about other programming languages, check out these two articles to learn how to install Python on your computer and use it to download financial data:
▶ Hadrien PUCHE How to Install and Run Python on Your Computer (A Step-by-Step Guide)
▶ Hadrien PUCHE How to download and model financial data with Python
About the Author
This article was written in September 2026 by Hadrien PUCHE (ESSEC Business School, Grande École Program, Master in Management, 2023-2027).
▶ Discover all posts by Hadrien PUCHE