Any financial analysis starts with data. Whether you want to analyze a stock, build a portfolio, measure risk, create a valuation model or develop trading strategies, the first step is always the same: obtaining financial data.
You could download data manually from websites such as Yahoo! Finance or Investing.com, but this quickly becomes tedious and time consuming. It also limits the amount of data you can work with.
Python allows us to automate this process and retrieve large amounts of financial information in just a few lines of code.
In this article, Hadrien Puche (ESSEC Business School, Grande École Program, Master in Management, 2023-2027) will help you understand how to:
- Download historical stock prices with Python
- Explore and visualize market data
- Compute basic statistics and historical distributions
- Compare multiple securities
- Perform a case study to measure market risk (Beta and Epsilon)
- Build the foundation needed for more advanced financial analysis
What financial data can we download?
Financial professionals use many different categories of data across individual assets as well as portfolios and funds.
Market data
- Individual asset prices (e.g., individual stocks, corporate bonds)
- Portfolios and funds (e.g., ETFs, mutual funds)
- Currency exchange rates
- Commodity prices
- Bond yields
Company fundamentals
- Revenue
- Earnings
- Margins
- Cash flows
Macroeconomic data
- Inflation
- Interest rates
- GDP growth
- Unemployment
Alternative data
- News
- Social media sentiment
- Satellite imagery
- Credit card spending
Not all data sources are freely available. Many professional investors rely on paid platforms such as Bloomberg, FactSet, Capital IQ or Morningstar to access standardized, high-frequency, and point-in-time data.
Fortunately, stock market data specifically can easily be accessed for free using Python for research and learning purposes.
In this article, we will use the open-source YFinance library to download historical market data, that you will then be able to model and use for any financial analysis project you may have.
A step-by-step guide
Follow the next steps to download you first financial data with Python 🙂
Step 1: Installing the required libraries
If you have not yet installed Python, refer to the setup guide published earlier in this series to configure your execution environment (such as Jupyter Notebook or Anaconda).
Once your environment is ready, install the required packages:
pip install yfinance pandas numpy matplotlibor inside Jupyter Notebook:
!pip install yfinance pandas numpy matplotlibWe will use:
- yfinance to retrieve market data
- pandas to manipulate data structures
- numpy for financial and mathematical operations
- matplotlib to create charts
Step 2: Import our Python packages
Every Python script starts by importing the packages we installed earlier. In Python, packages (or libraries) are reusable modules containing pre-written code and functions that extend Python’s core capabilities.
import yfinance as yf
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
The aliases (yf, pd, np, plt) make the code shorter and easier to read.
Step 3: Download our first data
To download financial data, we use a ticker symbol, a unique combination of letters representing any publicly traded security. For example, AAPL represents Apple.
Whenever we use a Python function, we can customize the output by passing variables/parameters into the function, such as period (e.g., "5y" for 5 years) or specific start and end dates.
As an example, let us download daily data for Apple stock price over the last 5 years (Yahoo! Finance ticker: AAPL). The data will be stored in a data frame (df) that we can name df_apple.
df_aapl = yf.download("AAPL", period="5y")

print(df_aapl.head())
You will obtain this table with the following columns:
- Close: closing price at the end of the trading day
- High: highest price during the trading day
- Low: lowest price during the trading day
- Open: opening price at the beginning of the trading day
- Volume: transaction volume during the trading day
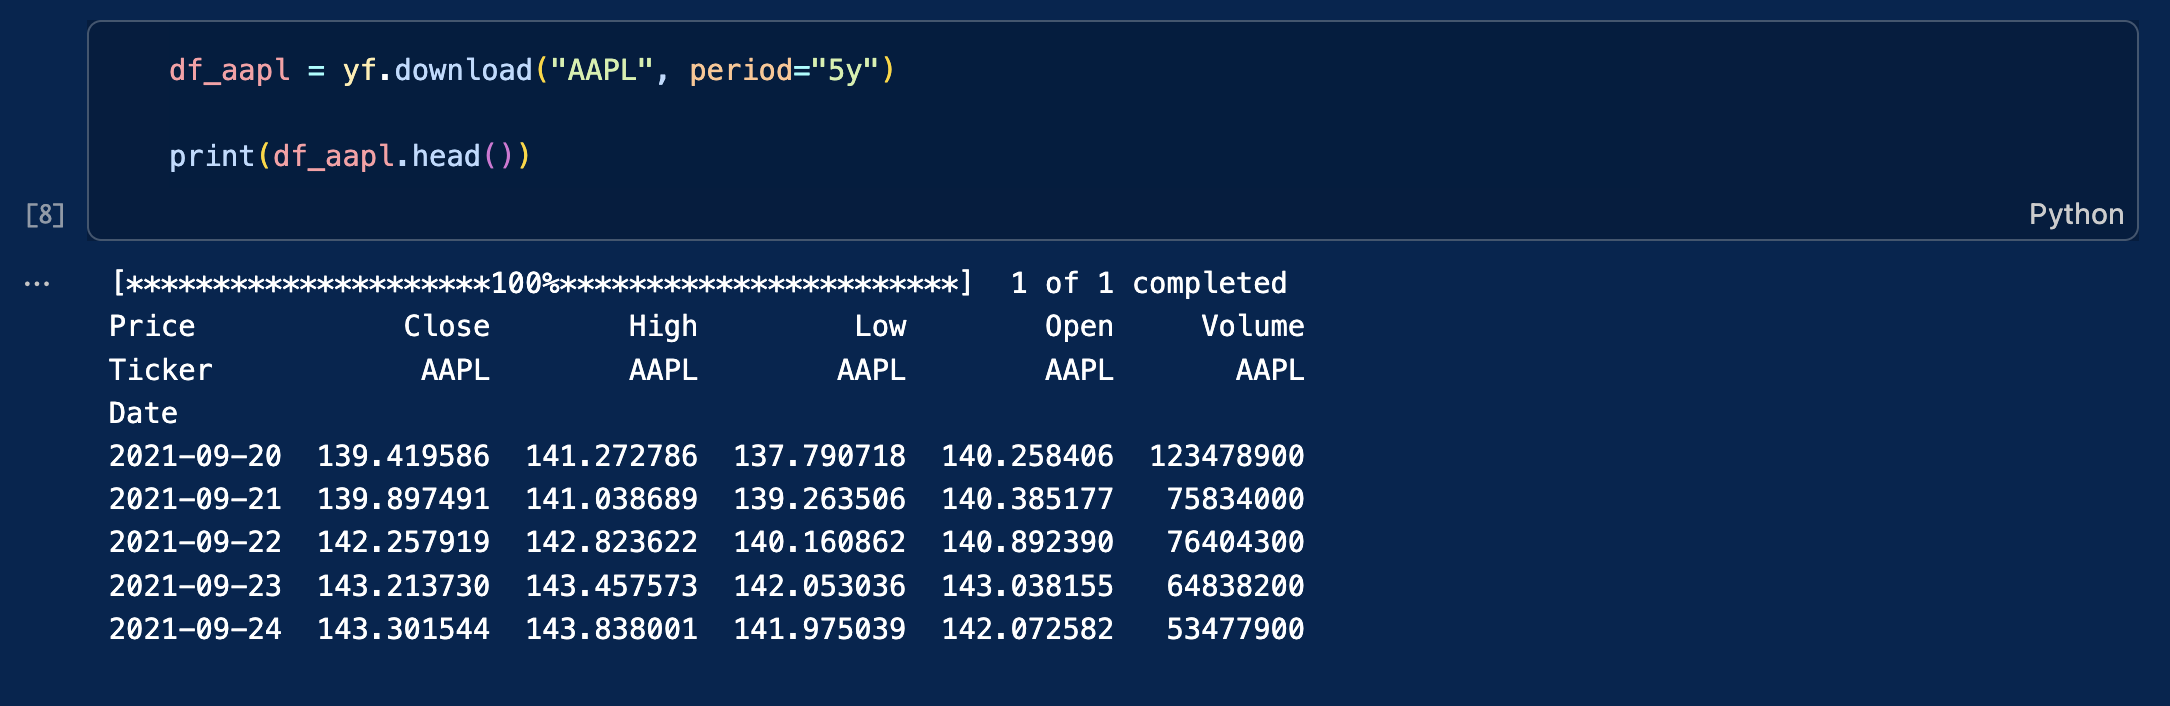
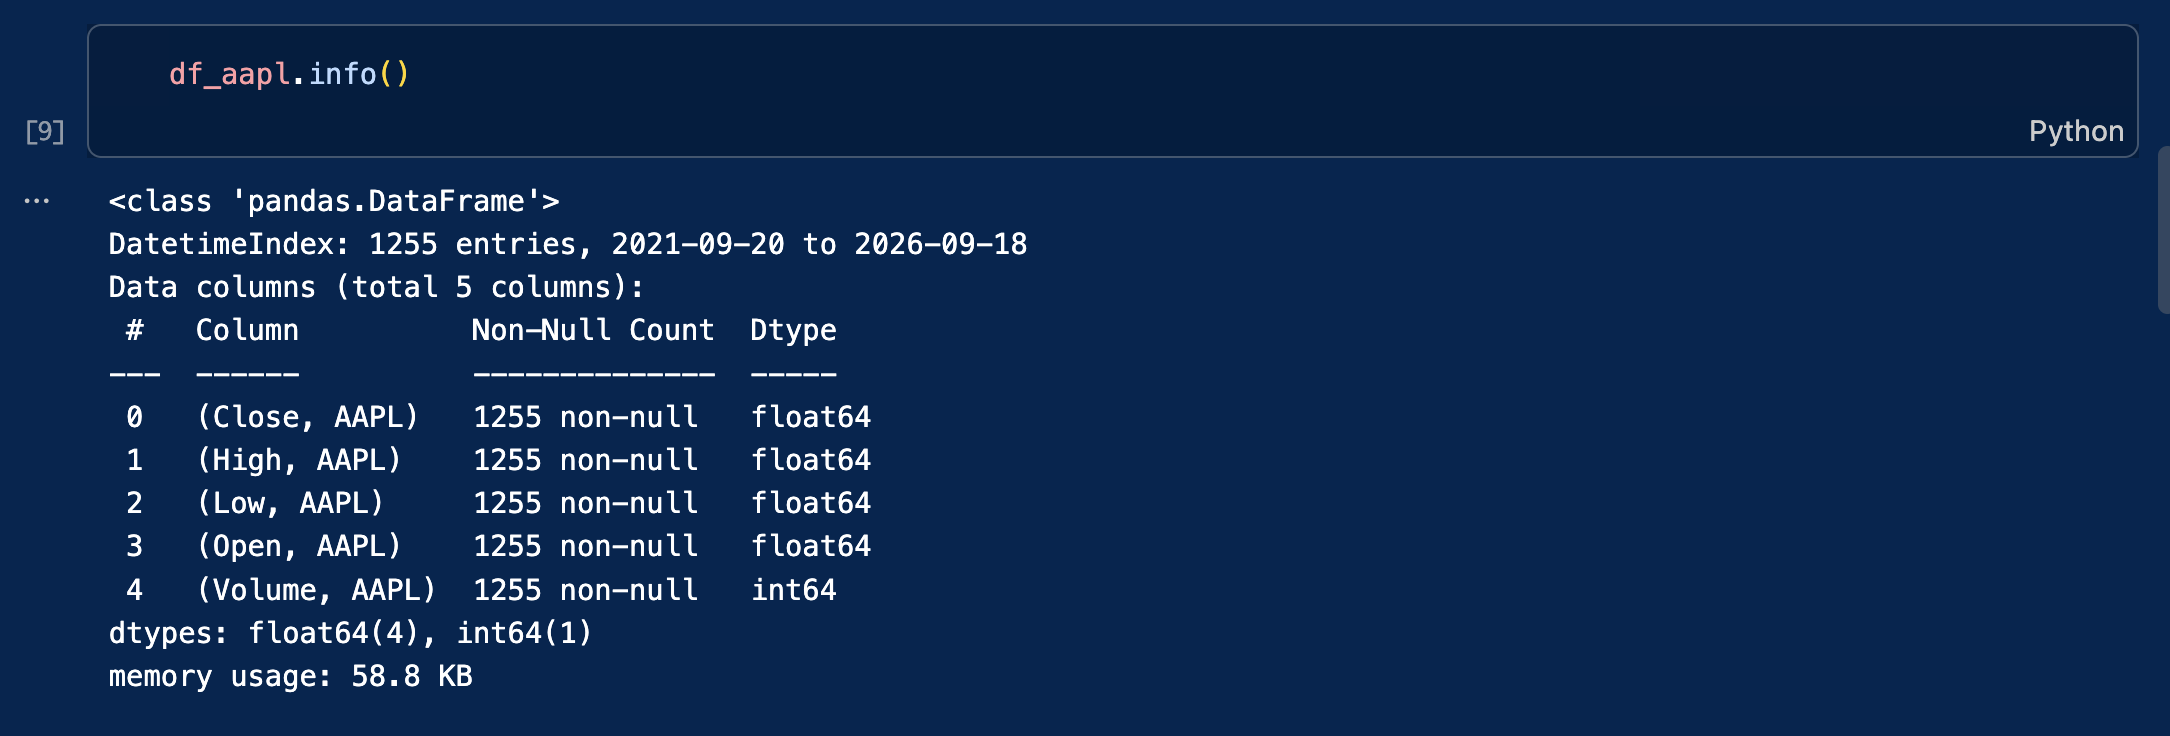
The data is stored in a Pandas DataFrame. This is a popular two-dimensional, tabular data structure with labeled axes (rows and columns).
To inspect its structure, type the following code:
df_aapl.info()
Step 4: Using more precise queries for historical context
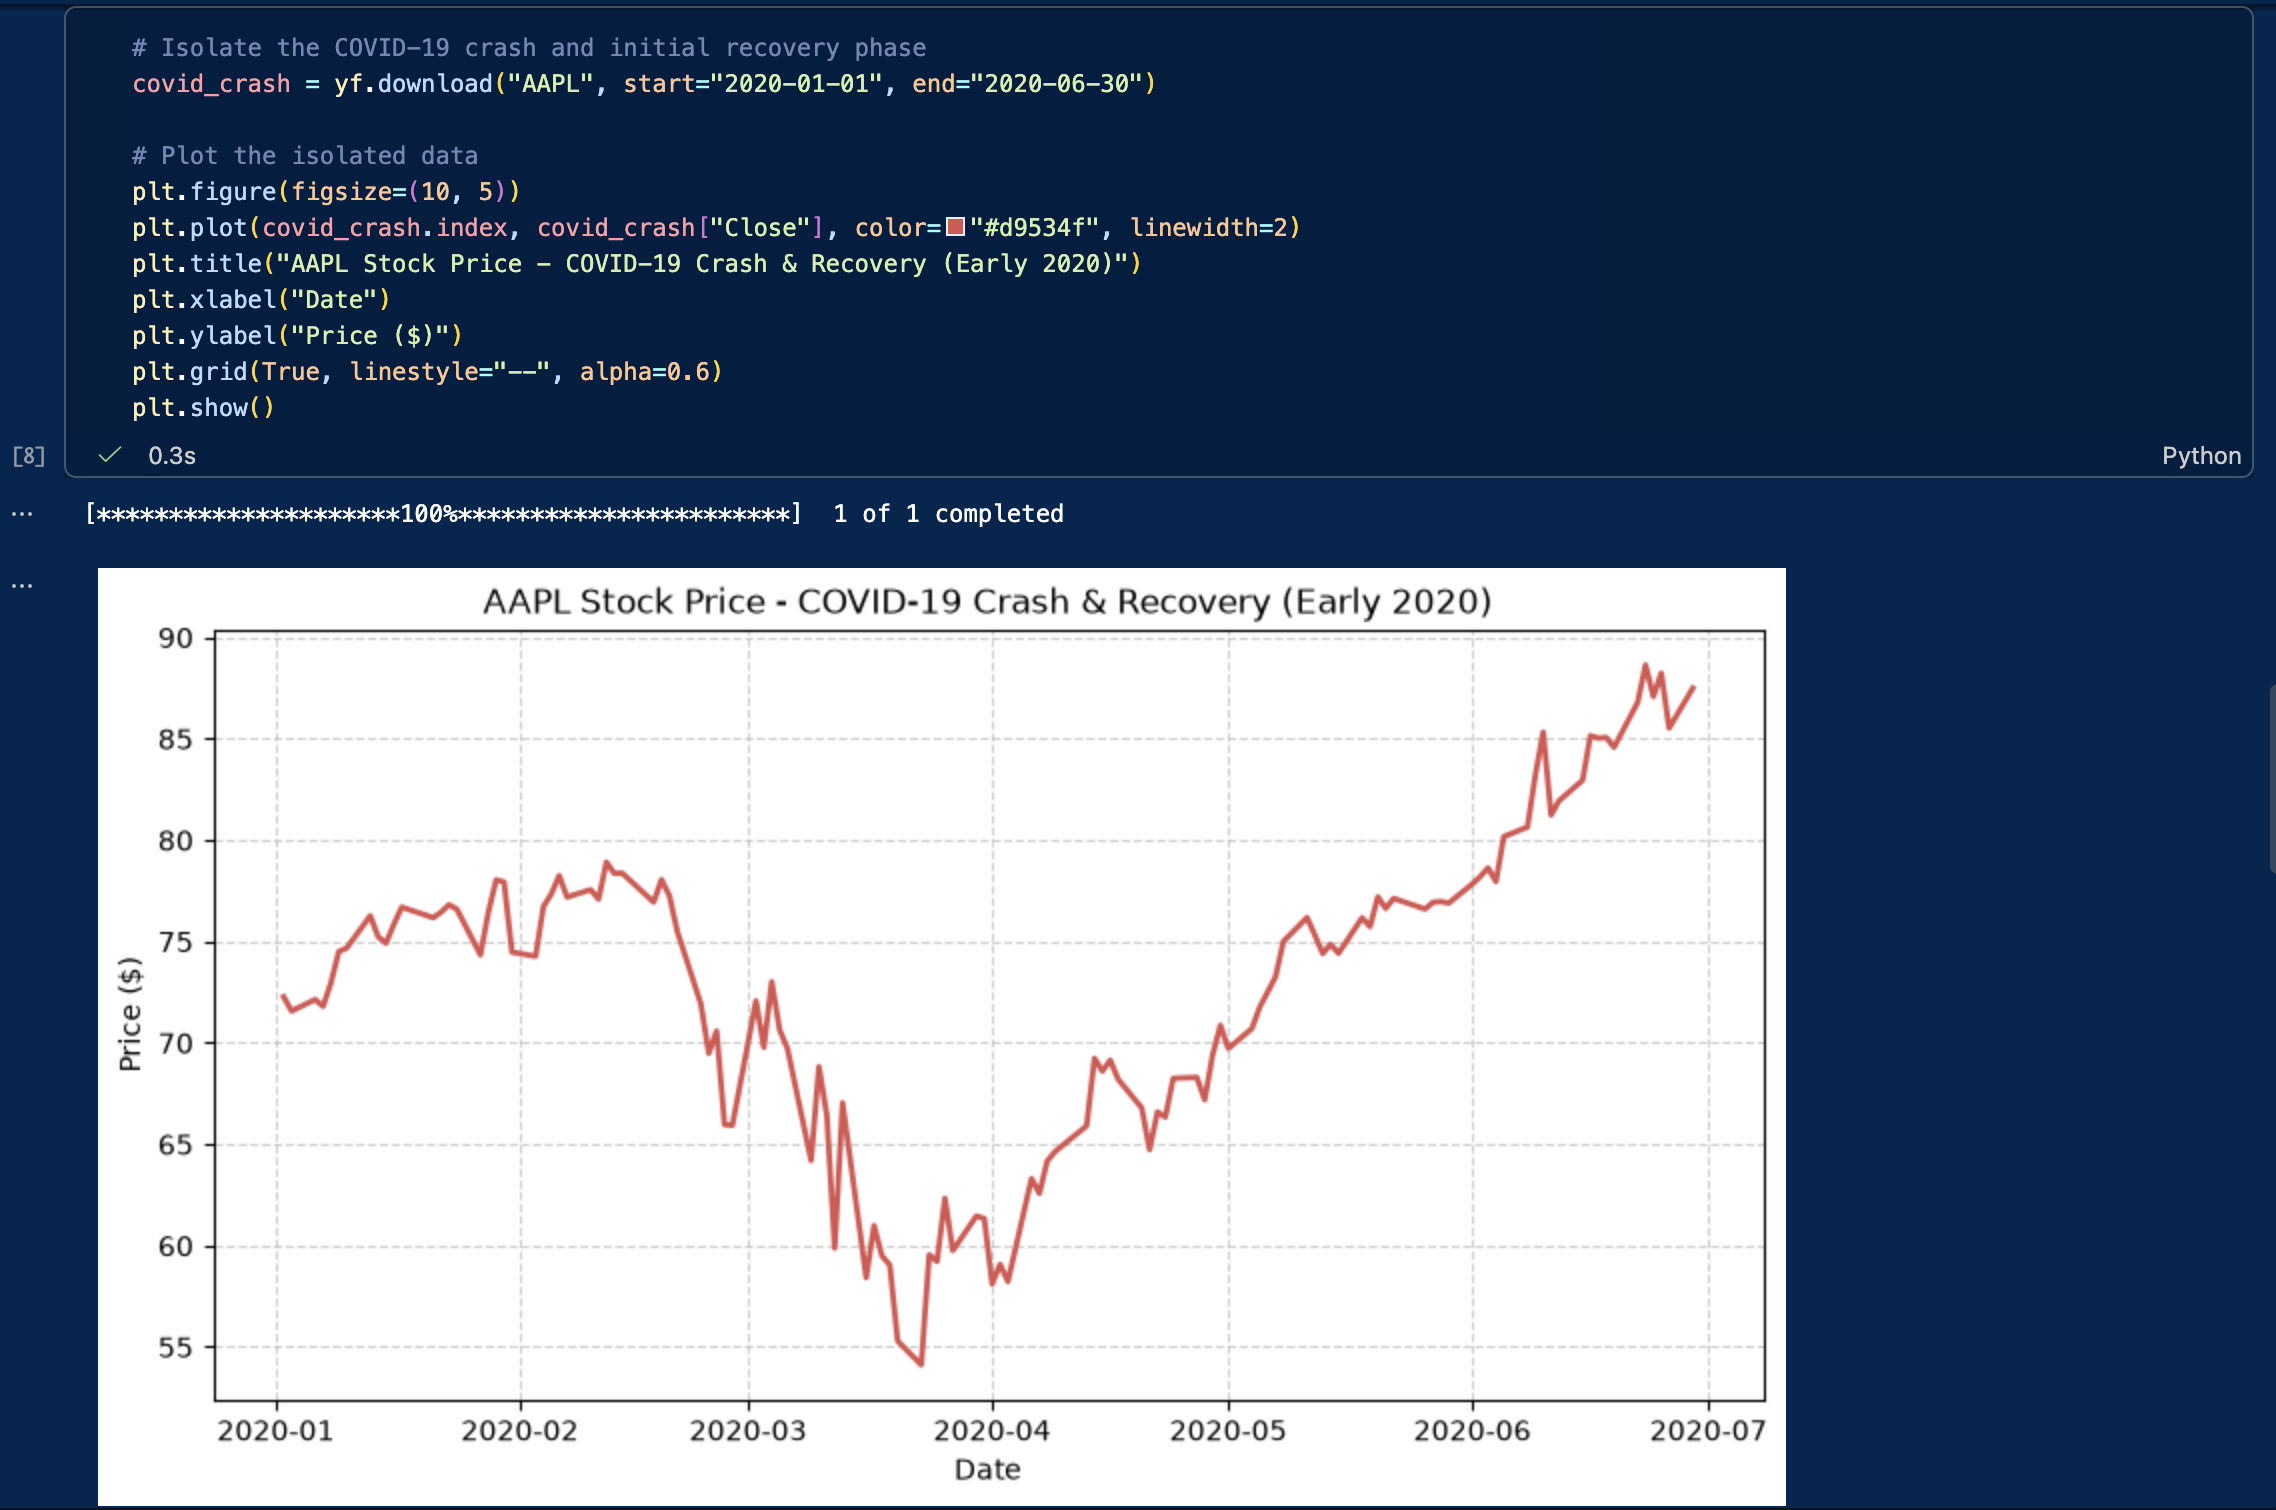
Instead of downloading a rolling period (like “5y”), we can isolate specific market events by passing exact start and end dates to the download function. As financial analysts, we routinely extract specific timeframes to understand how assets behave under macroeconomic stress.
For example, analyzing the COVID-19 market crash in early 2020 offers invaluable insights into extreme volatility, liquidity crunches, and rapid V-shaped recoveries. Let’s download and plot Apple’s stock specifically during the height of the pandemic shock (January to June 2020):
# Isolate the COVID-19 crash and initial recovery phase
covid_crash = yf.download("AAPL", start="2020-01-01", end="2020-06-30")

# Plot the isolated data
plt.figure(figsize=(10, 5))
plt.plot(covid_crash.index, covid_crash["Close"], color="#d9534f", linewidth=2)
plt.title("AAPL Stock Price - COVID-19 Crash & Recovery (Early 2020)")
plt.xlabel("Date")
plt.ylabel("Price ($)")
plt.grid(True, linestyle="--", alpha=0.6)
plt.show()
We could use this same technique to analyze other pivotal periods, such as:
- A central bank interest rate tightening cycle (e.g., the Fed’s 2022-2023 rate hikes)
- The 2008 Global Financial Crisis (if analyzing older datasets)
- Specific earnings announcement windows
Step 5: Downloading multiple stocks at the same time
Downloading multiple stocks is necessary for financial analysis that often requires comparing securities, building a portfolio, or testing trading strategies like pair trading.
Instead of issuing separate requests for each stock (which risks hitting API rate limits or misaligning dates), it is far more efficient to fetch all tickers at once in a single batch query.
To make this practical, let’s download the data for the “Magnificent Seven”. These seven mega-cap tech companies (Apple, Microsoft, Alphabet, Amazon, Meta, Nvidia, and Tesla) have heavily dominated market capitalization and driven a massive portion of the S&P 500’s returns in recent years.
# Define the Magnificent 7 tickers
mag7_tickers = ["AAPL", "MSFT", "GOOGL", "AMZN", "META", "NVDA", "TSLA"]

# Download the closing prices for all 7 stocks simultaneously
prices = yf.download(mag7_tickers, period="5y")["Close"]

print(prices.head())
The result is now again a matrix where each column represents a stock, and each row represents a trading day.
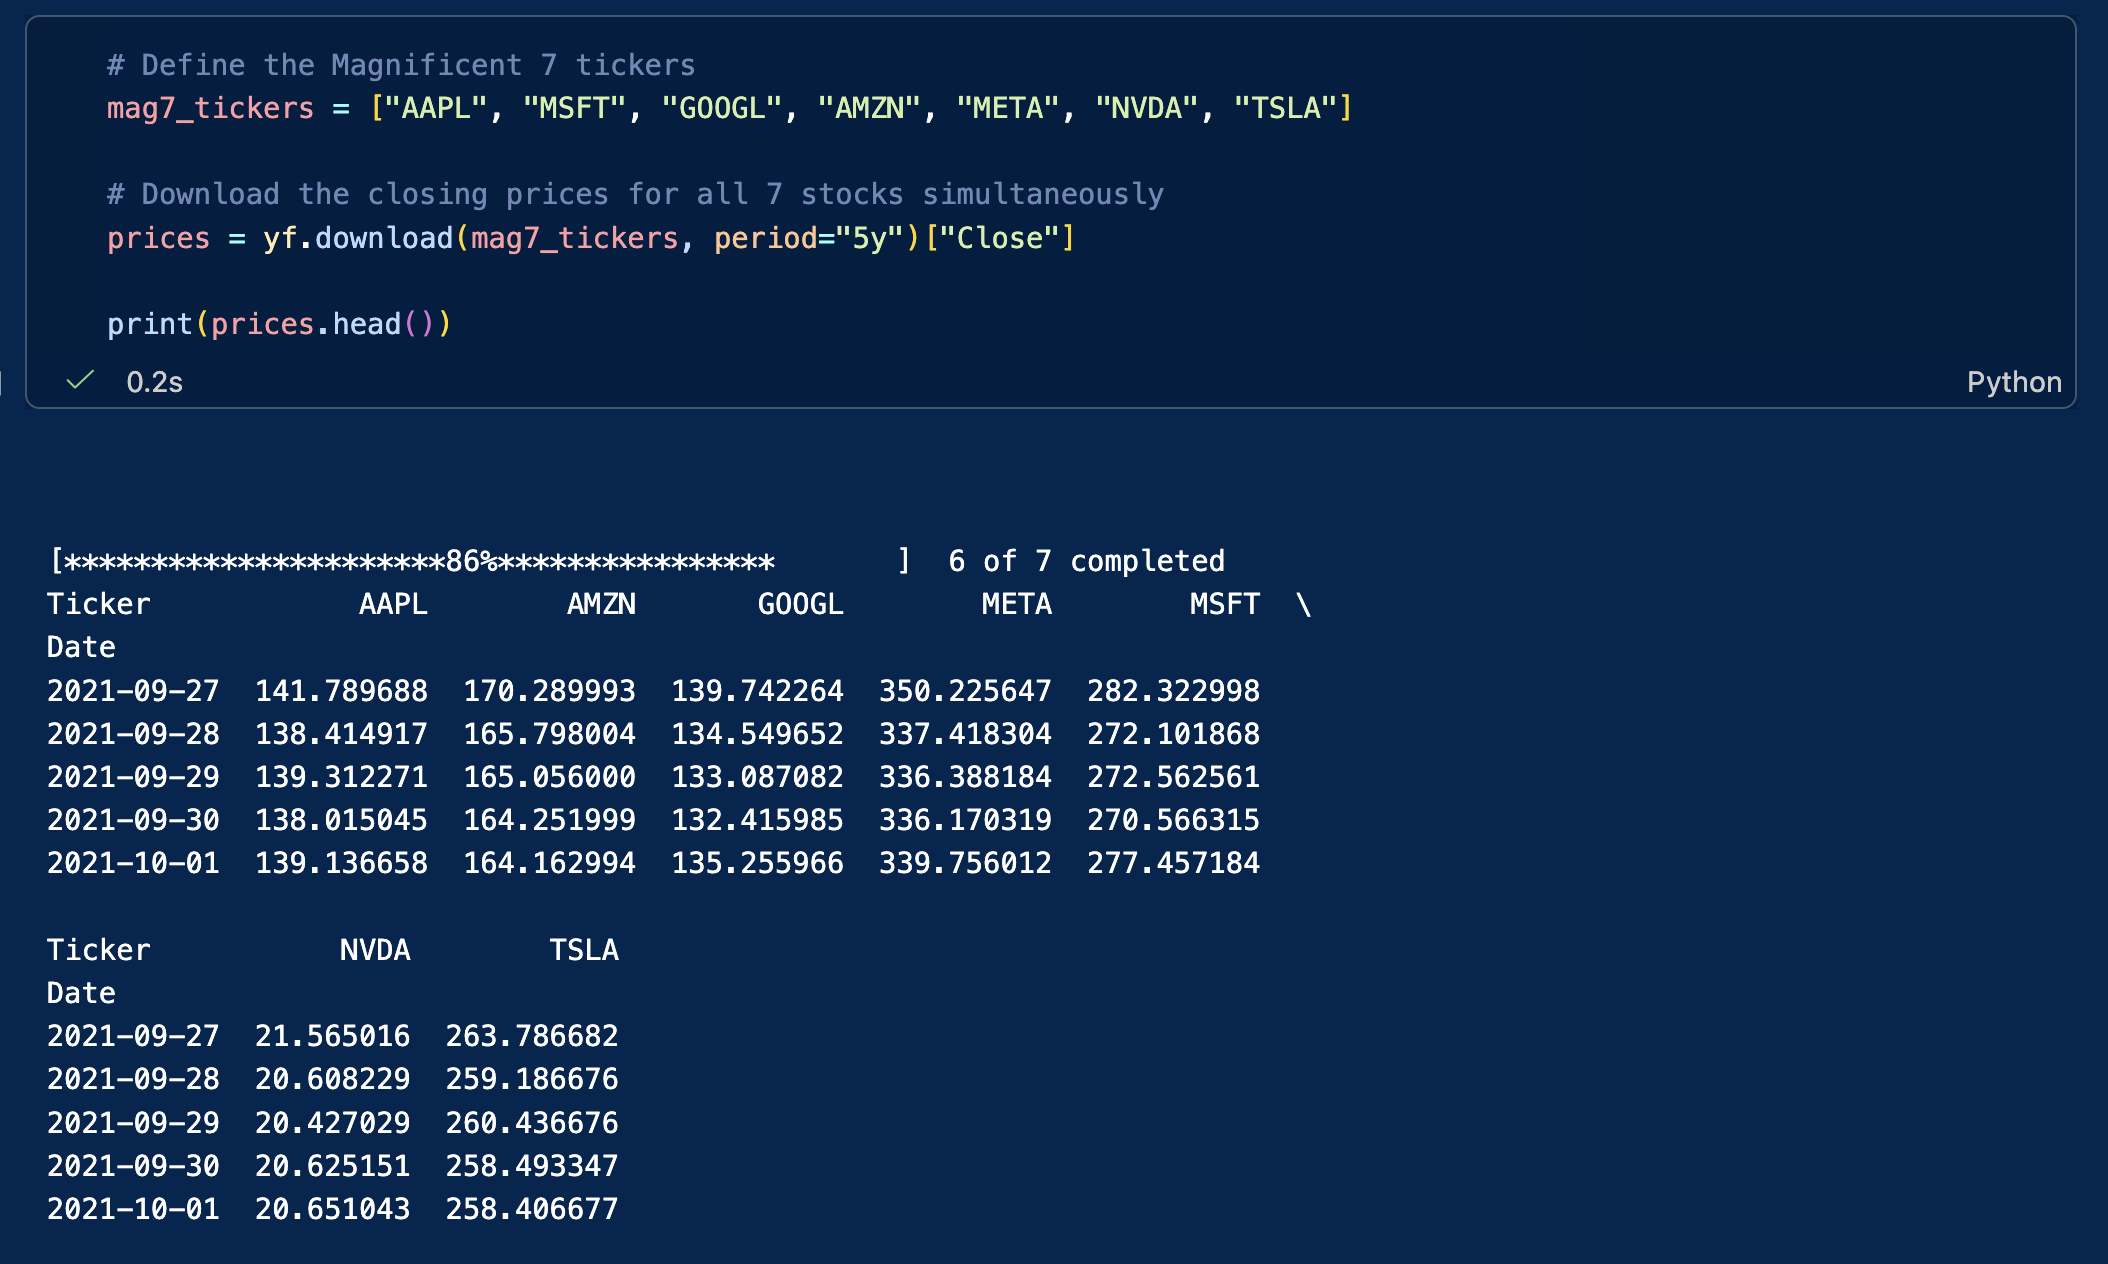
This table format is ideal for portfolio analysis, benchmarking, and performance comparisons, and can be used to draw any kind of graphs.
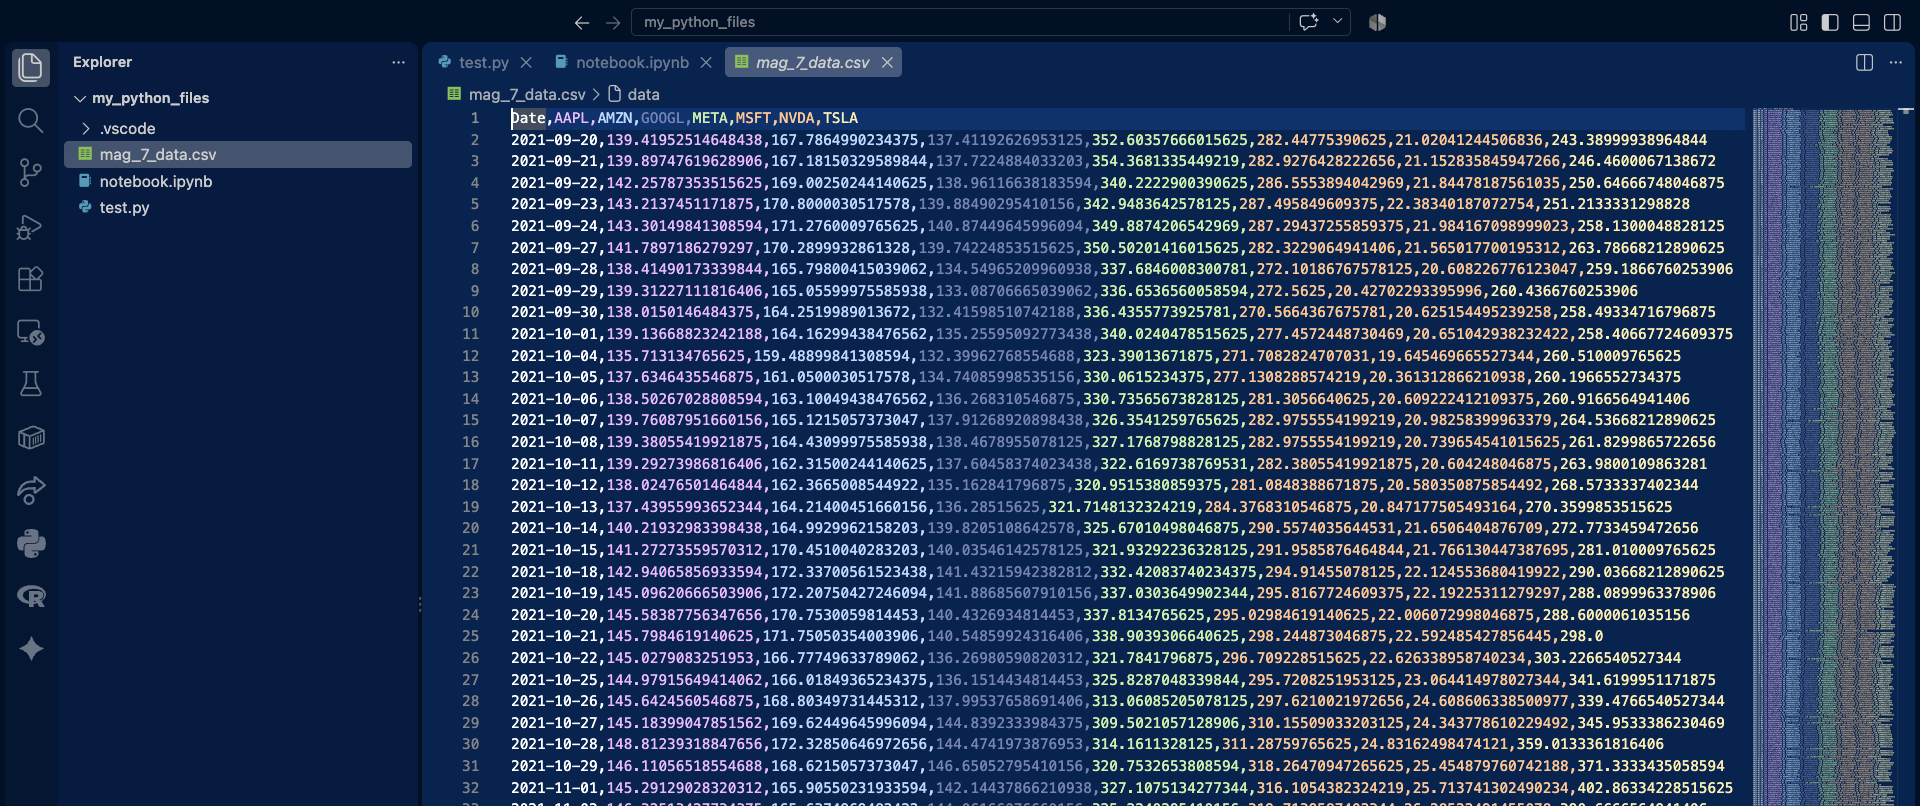
Note that the table’s columns are displayed in two groups. It’s a limitation of the Jupyter notebook. If you want to have a more convenient view over your dataframe, you can save it as a .csv file and open it.
# save the dataframe as a csv
prices.to_csv('mag_7_data.csv ')
Now that you successfully downloaded your financial data, let’s see how you can clean it and then use it.
Inspecting and cleaning the dataset
Financial datasets are rarely perfect. You will frequently encounter missing values (represented as NaN, or “Not a Number”) in datasets. These gaps usually occur due to trading halts, early market closures (like the day before Thanksgiving), or simple transmission glitches from the data provider.
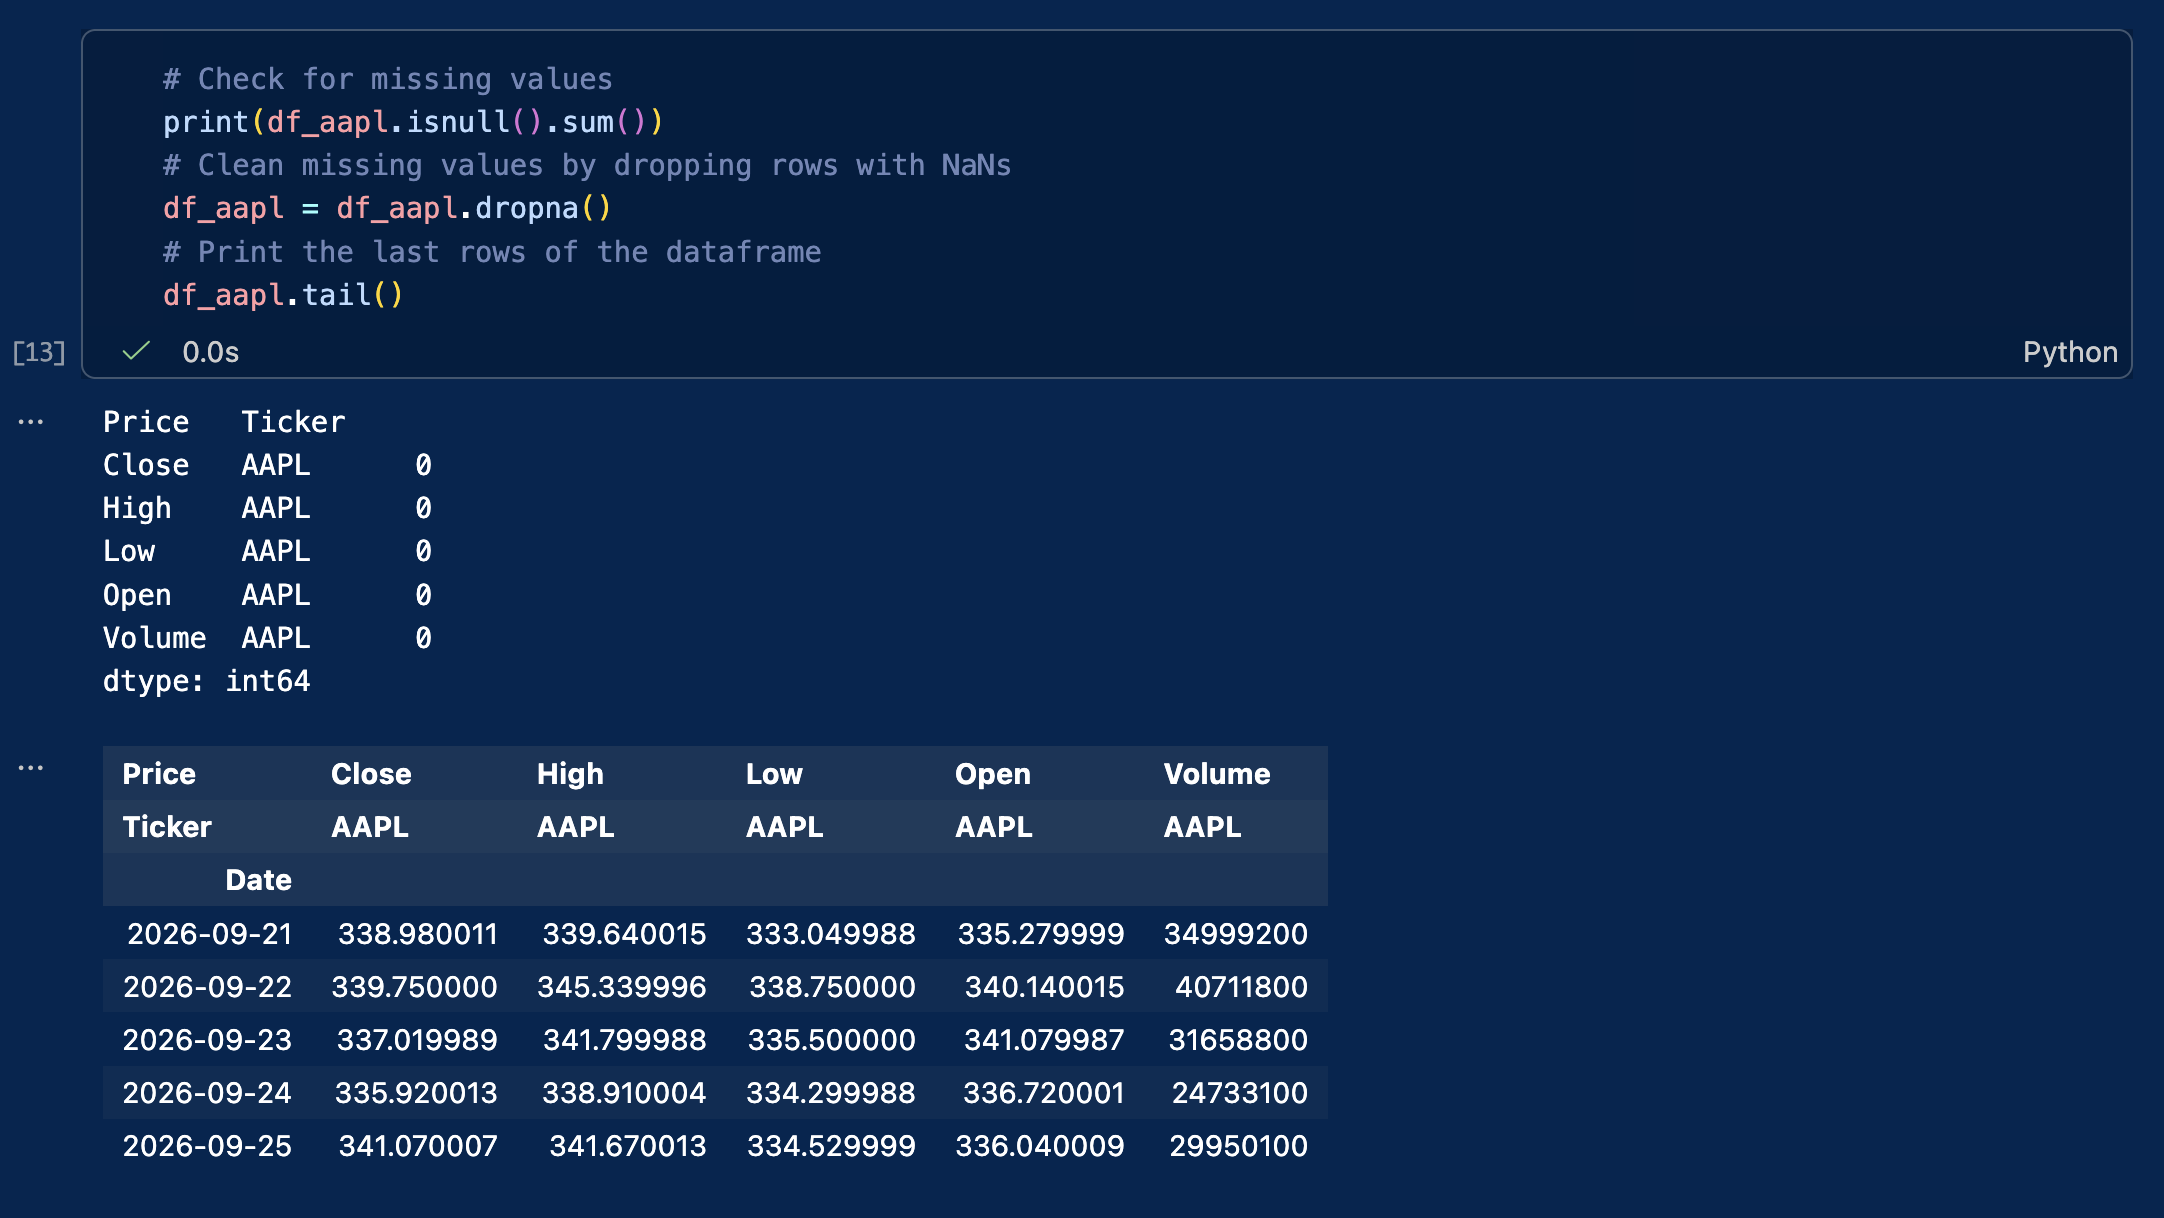
If left unaddressed, these missing data points will break your mathematical functions and severely distort your return and volatility calculations. The code below checks how many missing values exist in each column, and then removes (drops) any rows containing them. In some situations you might want to to forward-fill these gaps to preserve the timeline, but dropping them is the safest thing to do for now.
# Check for missing values
print(df_aapl.isnull().sum())
# Clean missing values by dropping rows with NaNs
df_aapl = df_aapl.dropna()
# Print the first rows of the dataframe
df_aapl.head()
df_aapl.head()
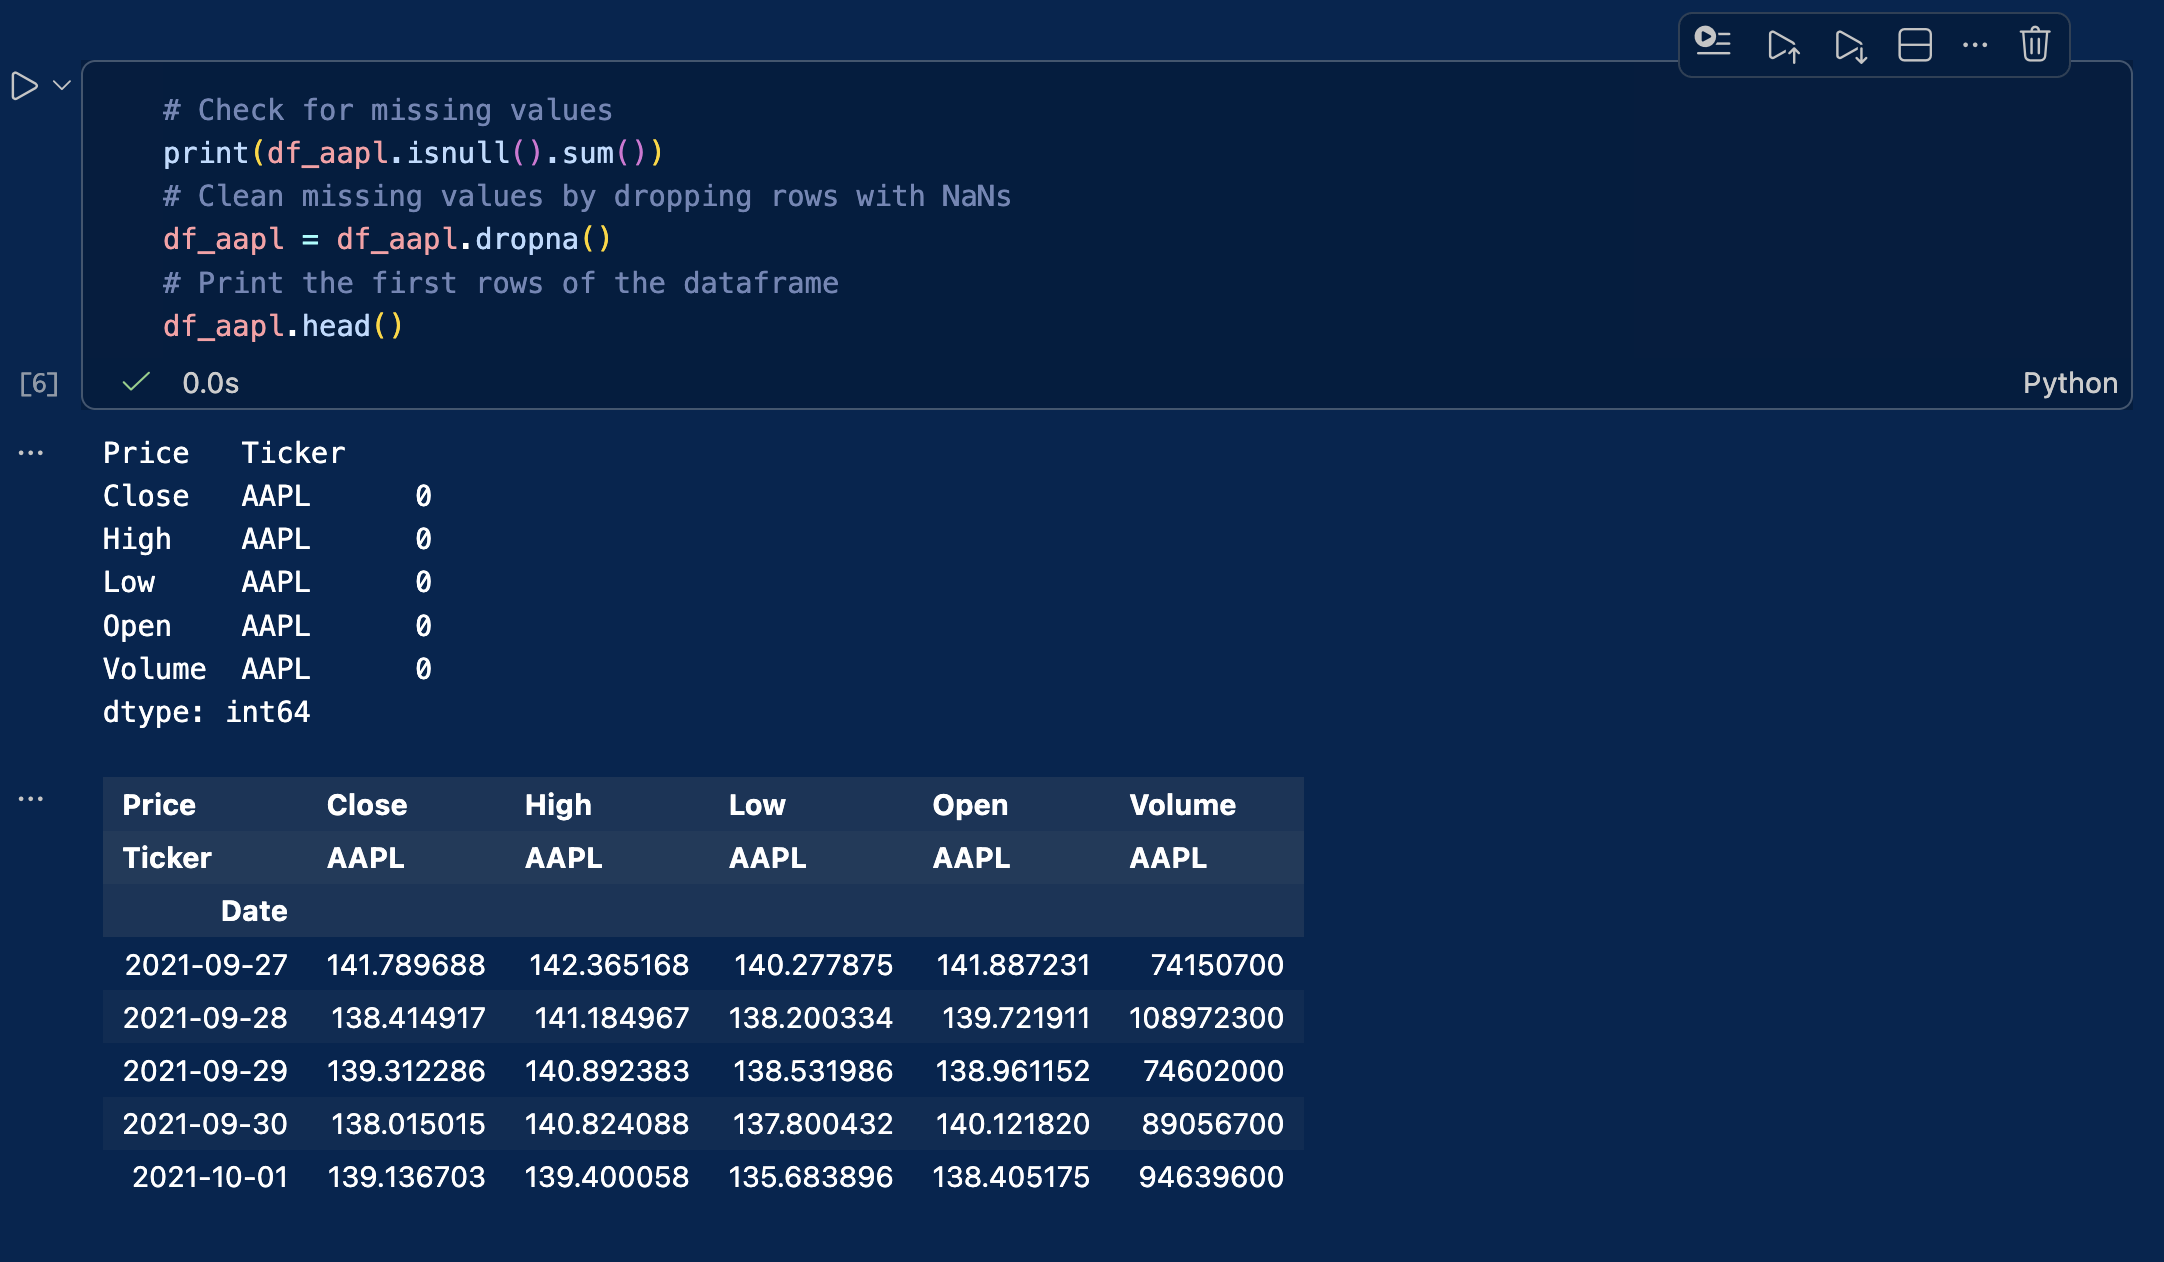
To view the last rows of the dataframe, replace head() by tail():
Visualizing the stock price with graphs or charts
Let’s create our first graph to visualize the evolution of Apple stock price.
plt.figure(figsize=(10, 5))
plt.plot(df_aapl.index, df_aapl["Close"], label="AAPL Close Price")
plt.title("Apple Stock Price")
plt.xlabel("Date")
plt.ylabel("Price ($)")
plt.legend()
plt.show()
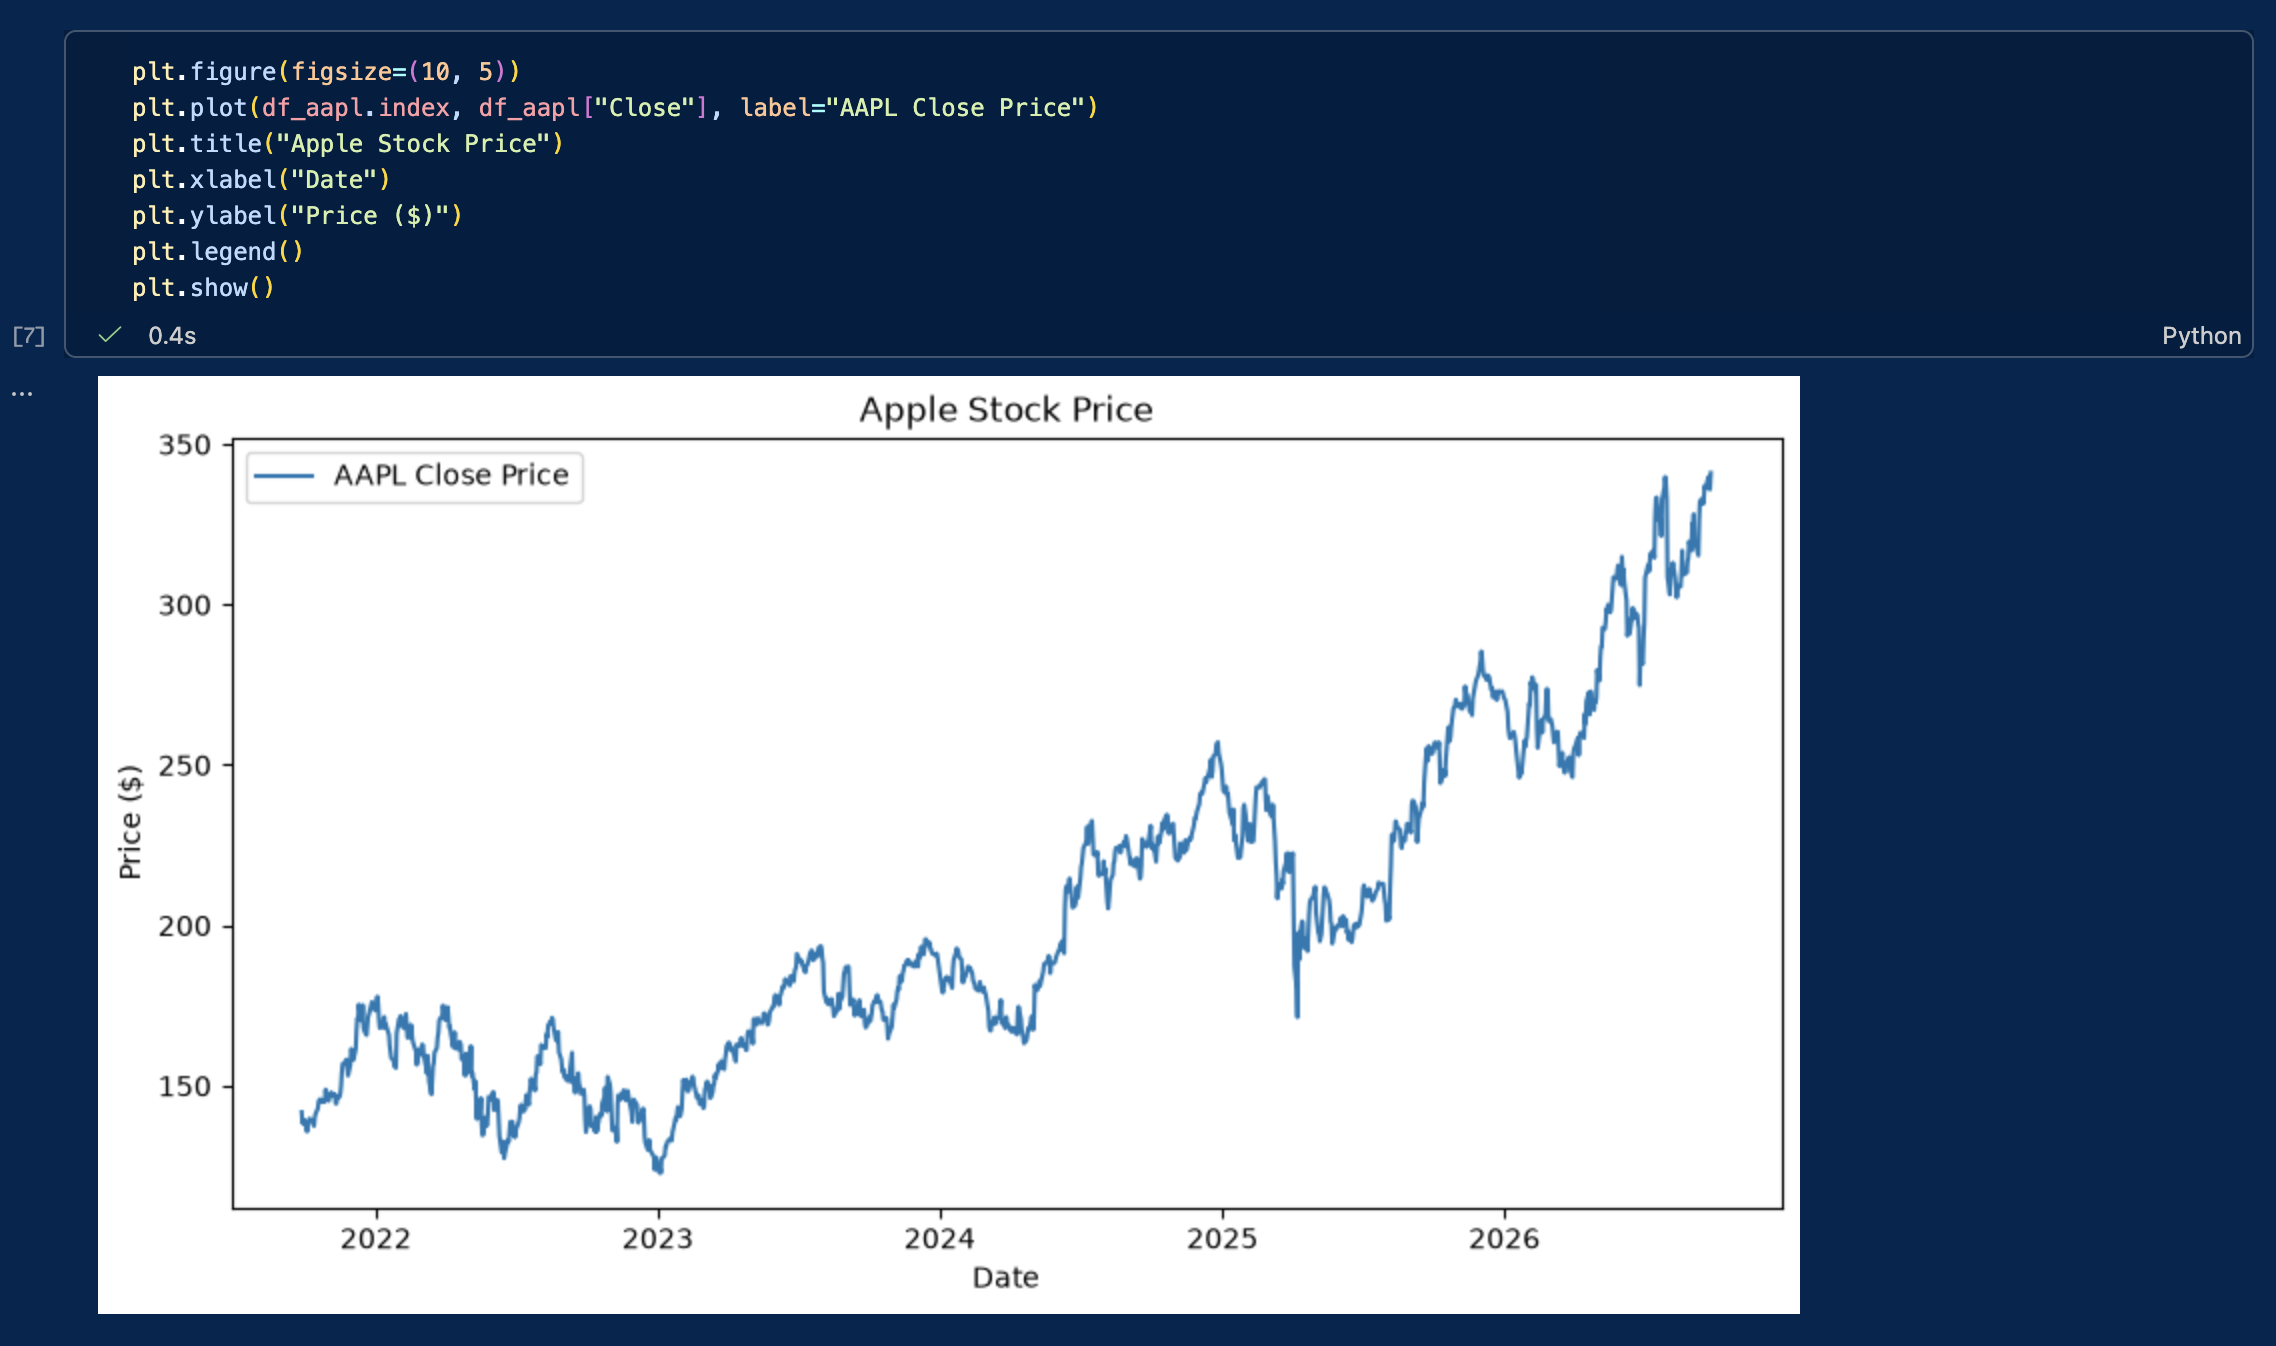
We have now:
- Downloaded market data from Yahoo! Finance
- Stored and cleaned the data in a dataframe
- Created a time-series plot to visualize stock prices
These core steps form the basis of empirical financial research and quantitative models.
Computing basic statistics & historical distributions
To evaluate stock performance and risk, we compute basic descriptive statistics for both prices and financial returns: minimum, maximum, mean, variance, standard deviation, skewness, and kurtosis.
# Calculate daily percentage returns
df_aapl['Return'] = df_aapl['Close'].pct_change()

# Compute summary statistics for Price and Returns
stats_df = pd.DataFrame({
    'Metric': ['Min', 'Max', 'Mean', 'Variance', 'Std Dev', 'Skewness', 'Kurtosis'],
    'Price ($)': [
        df_aapl['Close'].min().item(),
        df_aapl['Close'].max().item(),
        df_aapl['Close'].mean().item(),
        df_aapl['Close'].var().item(),
        df_aapl['Close'].std().item(),
        df_aapl['Close'].skew().item(),
        df_aapl['Close'].kurtosis().item()
    ],
    'Daily Return': [
        df_aapl['Return'].min().item(),
        df_aapl['Return'].max().item(),
        df_aapl['Return'].mean().item(),
        df_aapl['Return'].var().item(),
        df_aapl['Return'].std().item(),
        df_aapl['Return'].skew().item(),
        df_aapl['Return'].kurtosis().item()
    ]
})

print(stats_df)
Plotting Historical Distributions
Histograms display the frequency distribution of prices and daily returns, helping us inspect price trends, distribution symmetry, and tail risks.
fig, axes = plt.subplots(1, 2, figsize=(14, 5))

# Price distribution
axes[0].hist(df_aapl['Close'].dropna(), bins=30, color='skyblue', edgecolor='black')
axes[0].set_title('Historical Price Distribution')
axes[0].set_xlabel('Price ($)')
axes[0].set_ylabel('Frequency')

# Return distribution
axes[1].hist(df_aapl['Return'].dropna(), bins=50, color='salmon', edgecolor='black')
axes[1].set_title('Historical Daily Return Distribution')
axes[1].set_xlabel('Daily Return')
axes[1].set_ylabel('Frequency')

plt.tight_layout()
plt.show()
Harmonizing stock prices and computing returns
All stocks have different nominal prices. If Tesla trades at $350 and Nvidia at $220, it does not mean that Tesla is worth more than Nvidia or performed better.
To establish an accurate comparison across these assets, we must execute two fundamental computations:
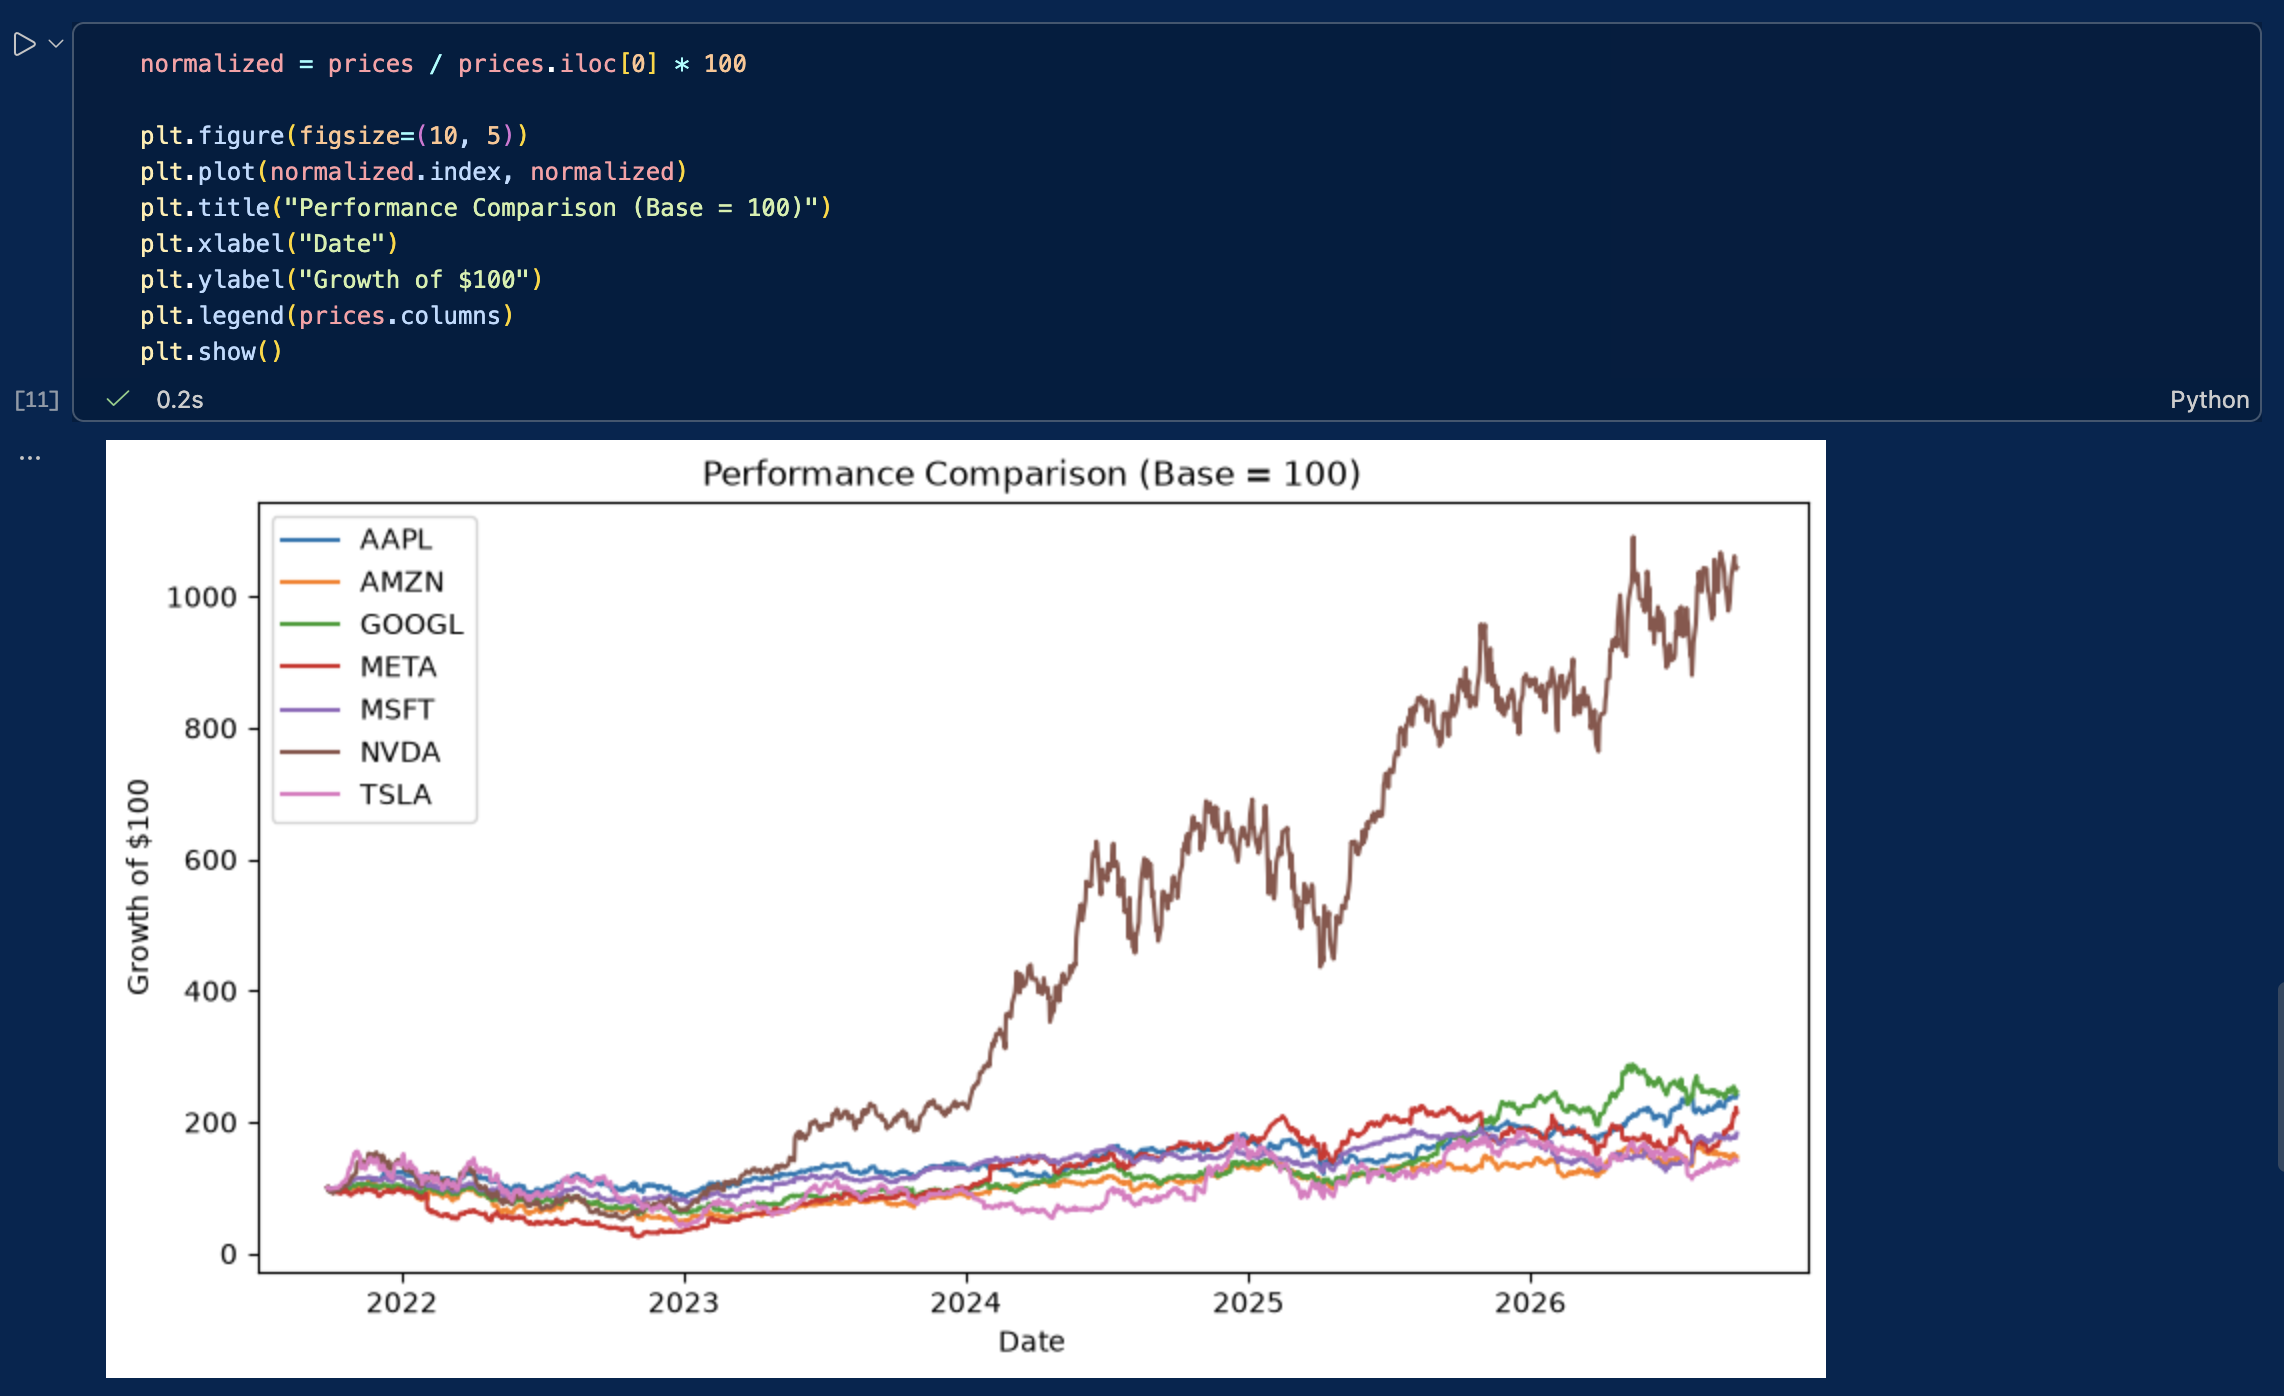
- Price harmonization: we normalize all historical time series to a base index of 100, to ensure a standardized starting point.
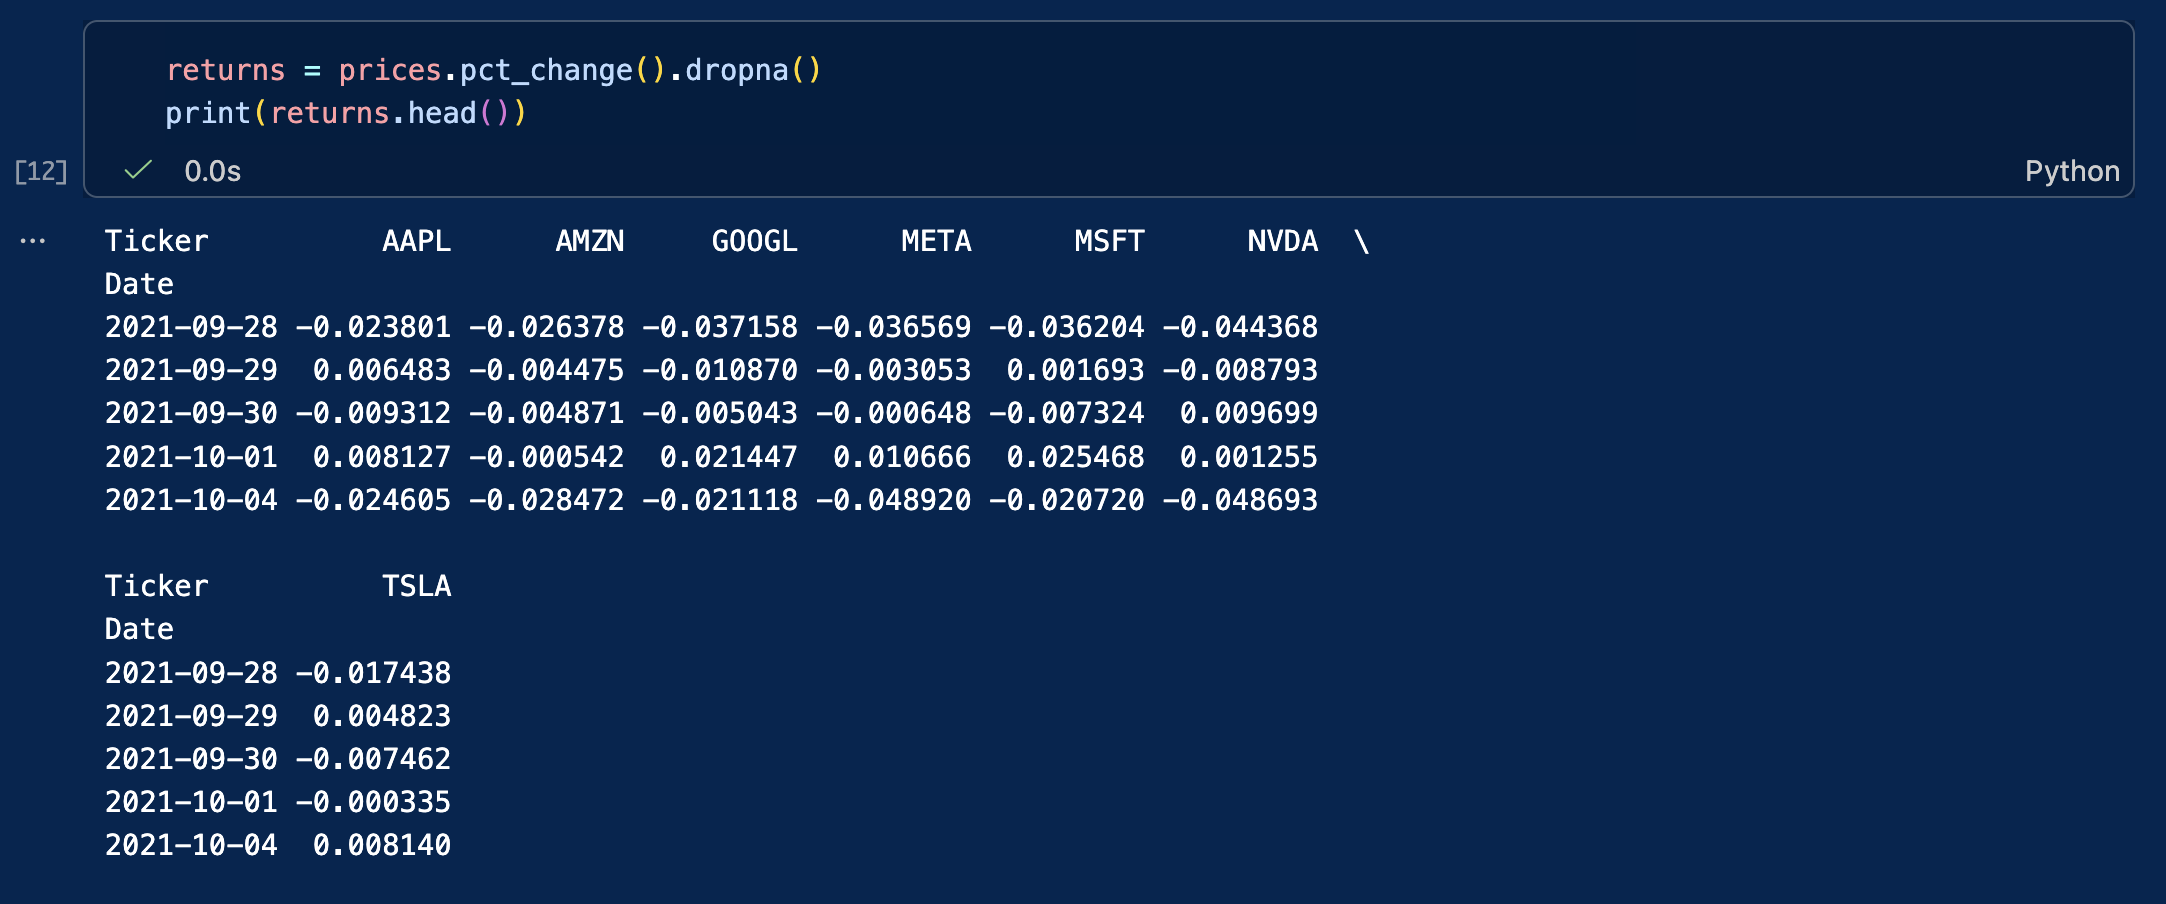
- Return calculation: we compute the periodic returns to get the actual performance in % rather than the absolute variation.
normalized = prices / prices.iloc[0] * 100

plt.figure(figsize=(10, 5))
plt.plot(normalized.index, normalized)
plt.title("Performance Comparison (Base = 100)")
plt.xlabel("Date")
plt.ylabel("Growth of $100")
plt.legend(prices.columns)
plt.show()
We can also compute daily returns across all stocks:
returns = prices.pct_change().dropna()
print(returns.head())
The chart now shows how much each investment would have grown from the same starting value.
This is a standard technique used by portfolio managers and equity analysts.
Case Study: The Capital Asset Pricing Model (CAPM)
In empirical finance, evaluating an individual asset requires isolating the return generated by the broader market from the return specific to the company itself. The Capital Asset Pricing Model (CAPM) provides the foundational framework to decompose this risk.
The model decomposes the return of an individual asset over a given time-period in three components: the risk-free rate, a market systematic factor and a firm specific factor. The model is expressed through the following equation:
rt = rf + β(rm – rf) + εt
Where:
- rt is the return of the stock (e.g., Apple).
- rf is the risk-free interest rate (e.g., the 13-week Treasury Bill,
^IRX). - β (Beta) represents the stock’s sensitivity to market movements (systematic risk).
- rm – rf is the excess return of the market index (e.g., the S&P 500,
^GSPC). - εt (Epsilon) represents the idiosyncratic return associated to firm-specific risk not explained by the market.
By downloading these three time series simultaneously, we can calculate the stock’s Beta and isolate its firm-specific residual risk.
# Download asset (AAPL), market benchmark (S&P 500), and risk-free rate (13-week T-Bill)
market_data = yf.download(["AAPL", "^GSPC", "^IRX"], start="2022-01-01", end="2024-12-31")["Close"].dropna()

# Compute daily percentage returns for the stock and the market
returns_df = market_data[["AAPL", "^GSPC"]].pct_change().dropna()

# Convert the annualized risk-free yield (^IRX) to a daily rate
daily_rf = (market_data["^IRX"] / 100) / 252
returns_df["Rf"] = daily_rf

# Calculate the excess returns: (r_t - r_f) and (r_m - r_f)
excess_aapl = returns_df["AAPL"] - returns_df["Rf"]
excess_market = returns_df["^GSPC"] - returns_df["Rf"]

# Compute Market Beta: Covariance(stock, market) / Variance(market)
cov_matrix = np.cov(excess_aapl, excess_market)
beta = cov_matrix[0, 1] / cov_matrix[1, 1]

# Isolate Epsilon (the firm-specific residual risk)
# Rearranging the CAPM equation: epsilon = (r_t - r_f) - beta * (r_m - r_f)
epsilon = excess_aapl - (beta * excess_market)

print(f"Calculated Beta: {beta:.4f}")
print(f"Mean Firm-Specific Return (Epsilon): {epsilon.mean():.6f}")
print(f"Idiosyncratic Risk (Epsilon Std Dev): {epsilon.std():.4f}")
Common pitfalls
When working with market data, beginners often run into the same issues:
- Using the wrong ticker symbol
- Comparing stocks without normalizing prices
- Forgetting that markets are closed on weekends and holidays
- Failing to clean and handle missing values (
NaN) in the dataset - Ignoring stock splits and dividends
Overall, don’t forget to always inspect and clean your data before starting your analysis.
Exercises
Exercise 1: Basic data retrieval and price visualization (MSFT)
Microsoft is a mature mega-cap technology company, and a cornerstone of most global equity portfolios. Retrieving and inspecting its historical data is a perfect starting point to practice basic YFinance commands.
Using the ticker symbol MSFT, download the last five years of daily market data.
Your tasks:
- Use the appropriate pandas functions to display the first 5 rows and the last 5 rows of the dataset to verify data integrity (checking for correct start/end dates).
- Generate a line chart plotting the closing price over the entire 5-year period to visualize its long-term market trend.
Exercise 2: time-series extraction and volume analysis on Tesla (TSLA)
Tesla is renowned for its high historical volatility and massive retail trading interest. The 2022-2024 window was particularly eventful for growth and electric vehicle stocks, marked by shifting supply chains and a rapid rise in interest rates. Isolating this exact timeframe allows us to analyze the stock’s behavior under changing macroeconomic conditions.
Using the ticker symbol TSLA, extract the market data for the precise calendar period from January 1, 2022, to December 31, 2024 (using the start and end parameters).
Your tasks:
- Identify the peak (highest closing price) and the trough (lowest closing price) over this period to grasp the magnitude of the stock’s price swings.
- Calculate the average daily trading volume, a fundamental metric used by analysts to assess market liquidity and ongoing investor interest.
Exercise 3: Comparative performance and risk profiling on Chinese tech companies
Chinese technology stocks often experience unique market cycles driven by distinct domestic regulatory environments and macroeconomic factors. Using their US-listed ADRs (American Depositary Receipts), compare the performance and risk characteristics of three major players:
- Alibaba (BABA)
- Baidu (BIDU)
- PDD Holdings (PDD)
Questions:
- Which stock achieved the highest total cumulative return?
- Which stock was most volatile (highest standard deviation of daily returns)?
- Which one offered the best risk-adjusted profile (e.g., highest Sharpe ratio) over the period?
Download the solutions
To help you check your work and experiment further, you can download the complete Jupyter Notebook containing the full code, charts, and commentary for all exercises.
What’s next?
Now that you know how to download financial data, perform basic computations, and control for market risk, you are ready to delve into advanced quantitative and corporate finance topics.
About the Author
This article was written in September 2026 by Hadrien PUCHE (ESSEC Business School, Grande École Program, Master in Management, 2023-2027).
▶ Discover all articles by Hadrien PUCHE